Streamlining data collection for improved salmon population management

Sara Beery came to MIT as an assistant professor in MIT’s Department of Electrical Engineering and Computer Science (EECS) eager to focus on ecological challenges. She has fashioned her research career around the opportunity to apply her expertise in computer vision, machine learning, and data science to tackle real-world issues in conservation and sustainability. Beery was drawn to the Institute’s commitment to “computing for the planet,” and set out to bring her methods to global-scale environmental and biodiversity monitoring.

In the Pacific Northwest, salmon have a disproportionate impact on the health of their ecosystems, and their complex reproductive needs have attracted Beery’s attention. Each year, millions of salmon embark on a migration to spawn. Their journey begins in freshwater stream beds where the eggs hatch. Young salmon fry (newly hatched salmon) make their way to the ocean, where they spend several years maturing to adulthood. As adults, the salmon return to the streams where they were born in order to spawn, ensuring the continuation of their species by depositing their eggs in the gravel of the stream beds. Both male and female salmon die shortly after supplying the river habitat with the next generation of salmon. 

Throughout their migration, salmon support a wide range of organisms in the ecosystems they pass through. For example, salmon bring nutrients like carbon and nitrogen from the ocean upriver, enhancing their availability to those ecosystems. In addition, salmon are key to many predator-prey relationships: They serve as a food source for various predators, such as bears, wolves, and birds, while helping to control other populations, like insects, through predation. After they die from spawning, the decomposing salmon carcasses also replenish valuable nutrients to the surrounding ecosystem. The migration of salmon not only sustains their own species but plays a critical role in the overall health of the rivers and oceans they inhabit. 

At the same time, salmon populations play an important role both economically and culturally in the region. Commercial and recreational salmon fisheries contribute significantly to the local economy. And for many Indigenous peoples in the Pacific northwest, salmon hold notable cultural value, as they have been central to their diets, traditions, and ceremonies. 

Monitoring salmon migration

Increased human activity, including overfishing and hydropower development, together with habitat loss and climate change, have had a significant impact on salmon populations in the region. As a result, effective monitoring and management of salmon fisheries is important to ensure balance among competing ecological, cultural, and human interests. Accurately counting salmon during their seasonal migration to their natal river to spawn is essential in order to track threatened populations, assess the success of recovery strategies, guide fishing season regulations, and support the management of both commercial and recreational fisheries. Precise population data help decision-makers employ the best strategies to safeguard the health of the ecosystem while accommodating human needs. Monitoring salmon migration is a labor-intensive and inefficient undertaking.

Beery is currently leading a research project that aims to streamline salmon monitoring using cutting-edge computer vision methods. This project fits within Beery’s broader research interest, which focuses on the interdisciplinary space between artificial intelligence, the natural world, and sustainability. Its relevance to fisheries management made it a good fit for funding from MIT’s Abdul Latif Jameel Water and Food Systems Lab (J-WAFS). Beery’s 2023 J-WAFS seed grant was the first research funding she was awarded since joining the MIT faculty.  

Historically, monitoring efforts relied on humans to manually count salmon from riverbanks using eyesight. In the past few decades, underwater sonar systems have been implemented to aid in counting the salmon. These sonar systems are essentially underwater video cameras, but they differ in that they use acoustics instead of light sensors to capture the presence of a fish. Use of this method requires people to set up a tent alongside the river to count salmon based on the output of a sonar camera that is hooked up to a laptop. While this system is an improvement to the original method of monitoring salmon by eyesight, it still relies significantly on human effort and is an arduous and time-consuming process. 

Automating salmon monitoring is necessary for better management of salmon fisheries. “We need these technological tools,” says Beery. “We can’t keep up with the demand of monitoring and understanding and studying these really complex ecosystems that we work in without some form of automation.”

Justin Kay, an MIT PhD student, presented to a group of nongovernmental organizations, tribes, and state and federal departments of fish and wildlife in Seattle. Photo courtesy of Justin Kay

In order to automate counting of migrating salmon populations in the Pacific Northwest, the project team, including Justin Kay, a PhD student in EECS, has been collecting data in the form of videos from sonar cameras at different rivers. The team annotates a subset of the data to train the computer vision system to autonomously detect and count the fish as they migrate. Kay describes the process of how the model counts each migrating fish: “The computer vision algorithm is designed to locate a fish in the frame, draw a box around it, and then track it over time. If a fish is detected on one side of the screen and leaves on the other side of the screen, then we count it as moving upstream.” On rivers where the team has created training data for the system, it has produced strong results, with only 3 to 5 percent counting error. This is well below the target that the team and partnering stakeholders set of no more than a 10 percent counting error. 

Testing and deployment: Balancing human effort and use of automation

The researchers’ technology is being deployed to monitor the migration of salmon on the newly restored Klamath River. Four dams on the river were recently demolished, making it the largest dam removal project in U.S. history. The dams came down after a more than 20-year-long campaign to remove them, which was led by Klamath tribes, in collaboration with scientists, environmental organizations, and commercial fishermen. After the removal of the dams, 240 miles of the river now flow freely and nearly 800 square miles of habitat are accessible to salmon. Beery notes the almost immediate regeneration of salmon populations in the Klamath River: “I think it was within eight days of the dam coming down, they started seeing salmon actually migrate upriver beyond the dam.” In a collaboration with California Trout, the team is currently processing new data to adapt and create a customized model that can then be deployed to help count the newly migrating salmon.

One challenge with the system revolves around training the model to accurately count the fish in unfamiliar environments with variations such as riverbed features, water clarity, and lighting conditions. These factors can significantly alter how the fish appear on the output of a sonar camera and confuse the computer model. When deployed in new rivers where no data have been collected before, like the Klamath, the performance of the system degrades and the margin of error increases substantially to 15-20 percent. 

The researchers constructed an automatic adaptation algorithm within the system to overcome this challenge and create a scalable system that can be deployed to any site without human intervention. This self-initializing technology works to automatically calibrate to the new conditions and environment to accurately count the migrating fish. In testing, the automatic adaptation algorithm was able to reduce the counting error down to the 10 to 15 percent range. The improvement in counting error with the self-initializing function means that the technology is closer to being deployable to new locations without much additional human effort. 

Enabling real-time management with the “Fishbox”

Another challenge faced by the research team was the development of an efficient data infrastructure. In order to run the computer vision system, the video produced by sonar cameras must be delivered via the cloud or by manually mailing hard drives from a river site to the lab. These methods have notable drawbacks: a cloud-based approach is limited due to lack of internet connectivity in remote river site locations, and shipping the data introduces problems of delay. 

Instead of relying on these methods, the team has implemented a power-efficient computer, coined the “Fishbox,” that can be used in the field to perform the processing. The Fishbox consists of a small, lightweight computer with optimized software that fishery managers can plug into their existing laptops and sonar cameras. The system is then capable of running salmon counting models directly at the sonar sites without the need for internet connectivity. This allows managers to make hour-by-hour decisions, supporting more responsive, real-time management of salmon populations.

Researchers convene on a river dock to discuss the use of automated sonar systems to monitor and manage salmon populations. Photo credit: Justin Kay

Community development

The team is also working to bring a community together around monitoring for salmon fisheries management in the Pacific Northwest. “It’s just pretty exciting to have stakeholders who are enthusiastic about getting access to [our technology] as we get it to work and having a tighter integration and collaboration with them,” says Beery. “I think particularly when you’re working on food and water systems, you need direct collaboration to help facilitate impact, because you’re ensuring that what you develop is actually serving the needs of the people and organizations that you are helping to support.”

This past June, Beery’s lab organized a workshop in Seattle that convened nongovernmental organizations, tribes, and state and federal departments of fish and wildlife to discuss the use of automated sonar systems to monitor and manage salmon populations. Kay notes that the workshop was an “awesome opportunity to have everybody sharing different ways that they’re using sonar and thinking about how the automated methods that we’re building could fit into that workflow.” The discussion continues now via a shared Slack channel created by the team, with over 50 participants. Convening this group is a significant achievement, as many of these organizations would not otherwise have had an opportunity to come together and collaborate. 

Looking forward

As the team continues to tune the computer vision system, refine their technology, and engage with diverse stakeholders — from Indigenous communities to fishery managers — the project is poised to make significant improvements to the efficiency and accuracy of salmon monitoring and management in the region. And as Beery advances the work of her MIT group, the J-WAFS seed grant is helping to keep challenges such as fisheries management in her sights.  

“The fact that the J-WAFS seed grant existed here at MIT enabled us to continue to work on this project when we moved here,” comments Beery, adding “it also expanded the scope of the project and allowed us to maintain active collaboration on what I think is a really important and impactful project.” 

As J-WAFS marks its 10th anniversary this year, the program aims to continue supporting and encouraging MIT faculty to pursue innovative projects that aim to advance knowledge and create practical solutions with real-world impacts on global water and food system challenges. 

Can deep learning transform heart failure prevention?

The ancient Greek philosopher and polymath Aristotle once concluded that the human heart is tri-chambered and that it was the single most important organ in the entire body, governing motion, sensation, and thought.

Today, we know that the human heart actually has four chambers and that the brain largely controls motion, sensation, and thought. But Aristotle was correct in observing that the heart is a vital organ, pumping blood to the rest of the body to reach other vital organs. When a life-threatening condition like heart failure strikes, the heart gradually loses the ability to supply other organs with enough blood and nutrients that enables them to function.

Researchers from MIT and Harvard Medical School recently published an open-access paper in Nature Communications Medicine, introducing a noninvasive deep learning approach that analyzes electrocardiogram (ECG) signals to accurately predict a patient’s risk of developing heart failure. In a clinical trial, the model showed results with accuracy comparable to gold-standard but more-invasive procedures, giving hope to those at risk of heart failure. The condition has recently seen a sharp increase in mortality, particularly among young adults, likely due to the growing prevalence of obesity and diabetes.

“This paper is a culmination of things I’ve talked about in other venues for several years,” says the paper’s senior author Collin Stultz, director of Harvard-MIT Program in Health Sciences and Technology and affiliate of the MIT Abdul Latif Jameel Clinic for Machine Learning in Health (Jameel Clinic). “The goal of this work is to identify those who are starting to get sick even before they have symptoms so that you can intervene early enough to prevent hospitalization.”

Of the heart’s four chambers, two are atria and two are ventricles — the right side of the heart has one atrium and one ventricle, and vice versa. In a healthy human heart, these chambers operate in a rhythmic synchrony: oxygen-poor blood flows into the heart via the right atrium. The right atrium contracts and the pressure generated pushes the blood into the right ventricle where the blood is then pumped into the lungs to be oxygenated. The oxygen-rich blood from the lungs then drains into the left atrium, which contracts, pumping the blood into the left ventricle. Another contraction follows, and the blood is ejected from the left ventricle via the aorta, flowing into veins branching out to the rest of the body.

“When the left atrial pressures become elevated, the blood drain from the lungs into the left atrium is impeded because it’s a higher-pressure system,” Stultz explains. In addition to being a professor of electrical engineering and computer science, Stultz is also a practicing cardiologist at Mass General Hospital (MGH). “The higher the pressure in the left atrium, the more pulmonary symptoms you develop — shortness of breath and so forth. Because the right side of the heart pumps blood through the pulmonary vasculature to the lungs, the elevated pressures in the left atrium translate to elevated pressures in the pulmonary vasculature.”

The current gold standard for measuring left atrial pressure is right heart catheterization (RHC), an invasive procedure that requires a thin tube (the catheter) attached to a pressure transmitter to be inserted into the right heart and pulmonary arteries. Physicians often prefer to assess risk noninvasively before resorting to RHC, by examining the patient’s weight, blood pressure, and heart rate.

But in Stultz’s view, these measures are coarse, as evidenced by the fact that one-in-four heart failure patients is readmitted to the hospital within 30 days. “What we are seeking is something that gives you information like that of an invasive device, other than a simple weight scale,” Stultz says.

In order to gather more comprehensive information on a patient’s heart condition, physicians typically use a 12-lead ECG, in which 10 adhesive patches are stuck onto the patient and linked with a machine that produces information from 12 different angles of the heart. However, 12-lead ECG machines are only accessible in clinical settings and they are also not typically used to assess heart failure risk.

Instead, what Stultz and other researchers propose is a Cardiac Hemodynamic AI monitoring System (CHAIS), a deep neural network capable of analyzing ECG data from a single lead — in other words, the patient only needs to have a single adhesive, commercially-available patch on their chest that they can wear outside of the hospital, untethered to a machine.

To compare CHAIS with the current gold standard, RHC, the researchers selected patients who were already scheduled for a catheterization and asked them to wear the patch 24 to 48 hours before the procedure, although patients were asked to remove the patch before catheterization took place. “When you get to within an hour-and-a-half [before the procedure], it’s 0.875, so it’s very, very good,” Stultz explains. “Thereby a measure from the device is equivalent and gives you the same information as if you were cathed in the next hour-and-a-half.”

“Every cardiologist understands the value of left atrial pressure measurements in characterizing cardiac function and optimizing treatment strategies for patients with heart failure,” says Aaron Aguirre SM ’03, PhD ’08, a cardiologist and critical care physician at MGH. “This work is important because it offers a noninvasive approach to estimating this essential clinical parameter using a widely available cardiac monitor.”

Aguirre, who completed a PhD in medical engineering and medical physics at MIT, expects that with further clinical validation, CHAIS will be useful in two key areas: first, it will aid in selecting patients who will most benefit from more invasive cardiac testing via RHC; and second, the technology could enable serial monitoring and tracking of left atrial pressure in patients with heart disease. “A noninvasive and quantitative method can help in optimizing treatment strategies in patients at home or in hospital,” Aguirre says. “I am excited to see where the MIT team takes this next.”

But the benefits aren’t just limited to patients — for patients with hard-to-manage heart failure, it becomes a challenge to keep them from being readmitted to the hospital without a permanent implant, taking up more space and more time of an already beleaguered and understaffed medical workforce.

The researchers have another ongoing clinical trial using CHAIS with MGH and Boston Medical Center that they hope to conclude soon to begin data analysis.

“In my view, the real promise of AI in health care is to provide equitable, state-of-the-art care to everyone, regardless of their socioeconomic status, background, and where they live,” Stultz says. “This work is one step towards realizing this goal.”

Validation technique could help scientists make more accurate forecasts

Should you grab your umbrella before you walk out the door? Checking the weather forecast beforehand will only be helpful if that forecast is accurate.

Spatial prediction problems, like weather forecasting or air pollution estimation, involve predicting the value of a variable in a new location based on known values at other locations. Scientists typically use tried-and-true validation methods to determine how much to trust these predictions.

But MIT researchers have shown that these popular validation methods can fail quite badly for spatial prediction tasks. This might lead someone to believe that a forecast is accurate or that a new prediction method is effective, when in reality that is not the case.

The researchers developed a technique to assess prediction-validation methods and used it to prove that two classical methods can be substantively wrong on spatial problems. They then determined why these methods can fail and created a new method designed to handle the types of data used for spatial predictions.

In experiments with real and simulated data, their new method provided more accurate validations than the two most common techniques. The researchers evaluated each method using realistic spatial problems, including predicting the wind speed at the Chicago O-Hare Airport and forecasting the air temperature at five U.S. metro locations.

Their validation method could be applied to a range of problems, from helping climate scientists predict sea surface temperatures to aiding epidemiologists in estimating the effects of air pollution on certain diseases.

“Hopefully, this will lead to more reliable evaluations when people are coming up with new predictive methods and a better understanding of how well methods are performing,” says Tamara Broderick, an associate professor in MIT’s Department of Electrical Engineering and Computer Science (EECS), a member of the Laboratory for Information and Decision Systems and the Institute for Data, Systems, and Society, and an affiliate of the Computer Science and Artificial Intelligence Laboratory (CSAIL).

Broderick is joined on the paper by lead author and MIT postdoc David R. Burt and EECS graduate student Yunyi Shen. The research will be presented at the International Conference on Artificial Intelligence and Statistics.

Evaluating validations

Broderick’s group has recently collaborated with oceanographers and atmospheric scientists to develop machine-learning prediction models that can be used for problems with a strong spatial component.

Through this work, they noticed that traditional validation methods can be inaccurate in spatial settings. These methods hold out a small amount of training data, called validation data, and use it to assess the accuracy of the predictor.

To find the root of the problem, they conducted a thorough analysis and determined that traditional methods make assumptions that are inappropriate for spatial data. Evaluation methods rely on assumptions about how validation data and the data one wants to predict, called test data, are related.

Traditional methods assume that validation data and test data are independent and identically distributed, which implies that the value of any data point does not depend on the other data points. But in a spatial application, this is often not the case.

For instance, a scientist may be using validation data from EPA air pollution sensors to test the accuracy of a method that predicts air pollution in conservation areas. However, the EPA sensors are not independent — they were sited based on the location of other sensors.

In addition, perhaps the validation data are from EPA sensors near cities while the conservation sites are in rural areas. Because these data are from different locations, they likely have different statistical properties, so they are not identically distributed.

“Our experiments showed that you get some really wrong answers in the spatial case when these assumptions made by the validation method break down,” Broderick says.

The researchers needed to come up with a new assumption.

Specifically spatial

Thinking specifically about a spatial context, where data are gathered from different locations, they designed a method that assumes validation data and test data vary smoothly in space.

For instance, air pollution levels are unlikely to change dramatically between two neighboring houses.

“This regularity assumption is appropriate for many spatial processes, and it allows us to create a way to evaluate spatial predictors in the spatial domain. To the best of our knowledge, no one has done a systematic theoretical evaluation of what went wrong to come up with a better approach,” says Broderick.

To use their evaluation technique, one would input their predictor, the locations they want to predict, and their validation data, then it automatically does the rest. In the end, it estimates how accurate the predictor’s forecast will be for the location in question. However, effectively assessing their validation technique proved to be a challenge.

“We are not evaluating a method, instead we are evaluating an evaluation. So, we had to step back, think carefully, and get creative about the appropriate experiments we could use,” Broderick explains.

First, they designed several tests using simulated data, which had unrealistic aspects but allowed them to carefully control key parameters. Then, they created more realistic, semi-simulated data by modifying real data. Finally, they used real data for several experiments.

Using three types of data from realistic problems, like predicting the price of a flat in England based on its location and forecasting wind speed, enabled them to conduct a comprehensive evaluation. In most experiments, their technique was more accurate than either traditional method they compared it to.

In the future, the researchers plan to apply these techniques to improve uncertainty quantification in spatial settings. They also want to find other areas where the regularity assumption could improve the performance of predictors, such as with time-series data.

This research is funded, in part, by the National Science Foundation and the Office of Naval Research.

Physicists measure a key aspect of superconductivity in “magic-angle” graphene

Superconducting materials are similar to the carpool lane in a congested interstate. Like commuters who ride together, electrons that pair up can bypass the regular traffic, moving through the material with zero friction.

But just as with carpools, how easily electron pairs can flow depends on a number of conditions, including the density of pairs that are moving through the material. This “superfluid stiffness,” or the ease with which a current of electron pairs can flow, is a key measure of a material’s superconductivity.

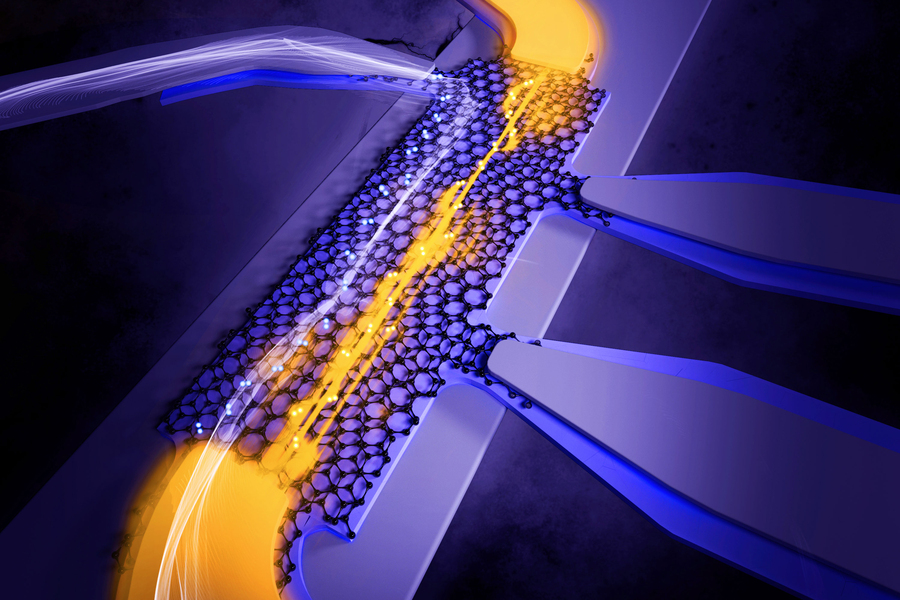
Physicists at MIT and Harvard University have now directly measured superfluid stiffness for the first time in “magic-angle” graphene — materials that are made from two or more atomically thin sheets of graphene twisted with respect to each other at just the right angle to enable a host of exceptional properties, including unconventional superconductivity.

This superconductivity makes magic-angle graphene a promising building block for future quantum-computing devices, but exactly how the material superconducts is not well-understood. Knowing the material’s superfluid stiffness will help scientists identify the mechanism of superconductivity in magic-angle graphene.

The team’s measurements suggest that magic-angle graphene’s superconductivity is primarily governed by quantum geometry, which refers to the conceptual “shape” of quantum states that can exist in a given material.

The results, which are reported today in the journal Nature, represent the first time scientists have directly measured superfluid stiffness in a two-dimensional material. To do so, the team developed a new experimental method which can now be used to make similar measurements of other two-dimensional superconducting materials.

“There’s a whole family of 2D superconductors that is waiting to be probed, and we are really just scratching the surface,” says study co-lead author Joel Wang, a research scientist in MIT’s Research Laboratory of Electronics (RLE).

The study’s co-authors from MIT’s main campus and MIT Lincoln Laboratory include co-lead author and former RLE postdoc Miuko Tanaka as well as Thao Dinh, Daniel Rodan-Legrain, Sameia Zaman, Max Hays, Bharath Kannan, Aziza Almanakly, David Kim, Bethany Niedzielski, Kyle Serniak, Mollie Schwartz, Jeffrey Grover, Terry Orlando, Simon Gustavsson, Pablo Jarillo-Herrero, and William D. Oliver, along with Kenji Watanabe and Takashi Taniguchi of the National Institute for Materials Science in Japan.

Magic resonance

Since its first isolation and characterization in 2004, graphene has proven to be a wonder substance of sorts. The material is effectively a single, atom-thin sheet of graphite consisting of a precise, chicken-wire lattice of carbon atoms. This simple configuration can exhibit a host of superlative qualities in terms of graphene’s strength, durability, and ability to conduct electricity and heat.

In 2018, Jarillo-Herrero and colleagues discovered that when two graphene sheets are stacked on top of each other, at a precise “magic” angle, the twisted structure — now known as magic-angle twisted bilayer graphene, or MATBG — exhibits entirely new properties, including superconductivity, in which electrons pair up, rather than repelling each other as they do in everyday materials. These so-called Cooper pairs can form a superfluid, with the potential to superconduct, meaning they could move through a material as an effortless, friction-free current.

“But even though Cooper pairs have no resistance, you have to apply some push, in the form of an electric field, to get the current to move,” Wang explains. “Superfluid stiffness refers to how easy it is to get these particles to move, in order to drive superconductivity.”

Today, scientists can measure superfluid stiffness in superconducting materials through methods that generally involve placing a material in a microwave resonator — a device which has a characteristic resonance frequency at which an electrical signal will oscillate, at microwave frequencies, much like a vibrating violin string. If a superconducting material is placed within a microwave resonator, it can change the device’s resonance frequency, and in particular, its “kinetic inductance,” by an amount that scientists can directly relate to the material’s superfluid stiffness.

However, to date, such approaches have only been compatible with large, thick material samples. The MIT team realized that to measure superfluid stiffness in atomically thin materials like MATBG would require a new approach.

“Compared to MATBG, the typical superconductor that is probed using resonators is 10 to 100 times thicker and larger in area,” Wang says. “We weren’t sure if such a tiny material would generate any measurable inductance at all.”

A captured signal

The challenge to measuring superfluid stiffness in MATBG has to do with attaching the supremely delicate material to the surface of the microwave resonator as seamlessly as possible.

“To make this work, you want to make an ideally lossless — i.e., superconducting — contact between the two materials,” Wang explains. “Otherwise, the microwave signal you send in will be degraded or even just bounce back instead of going into your target material.”

Will Oliver’s group at MIT has been developing techniques to precisely connect extremely delicate, two-dimensional materials, with the goal of building new types of quantum bits for future quantum-computing devices. For their new study, Tanaka, Wang, and their colleagues applied these techniques to seamlessly connect a tiny sample of MATBG to the end of an aluminum microwave resonator. To do so, the group first used conventional methods to assemble MATBG, then sandwiched the structure between two insulating layers of hexagonal boron nitride, to help maintain MATBG’s atomic structure and properties.

“Aluminum is a material we use regularly in our superconducting quantum computing research, for example, aluminum resonators to read out aluminum quantum bits (qubits),” Oliver explains. “So, we thought, why not make most of the resonator from aluminum, which is relatively straightforward for us, and then add a little MATBG to the end of it? It turned out to be a good idea.”

“To contact the MATBG, we etch it very sharply, like cutting through layers of a cake with a very sharp knife,” Wang says. “We expose a side of the freshly-cut MATBG, onto which we then deposit aluminum — the same material as the resonator — to make a good contact and form an aluminum lead.”

The researchers then connected the aluminum leads of the MATBG structure to the larger aluminum microwave resonator. They sent a microwave signal through the resonator and measured the resulting shift in its resonance frequency, from which they could infer the kinetic inductance of the MATBG.

When they converted the measured inductance to a value of superfluid stiffness, however, the researchers found that it was much larger than what conventional theories of superconductivity would have predicted. They had a hunch that the surplus had to do with MATBG’s quantum geometry — the way the quantum states of electrons correlate to one another.

We saw a tenfold increase in superfluid stiffness compared to conventional expectations, with a temperature dependence consistent with what the theory of quantum geometry predicts,” Tanaka says. “This was a ‘smoking gun’ that pointed to the role of quantum geometry in governing superfluid stiffness in this two-dimensional material.”

“This work represents a great example of how one can use sophisticated quantum technology currently used in quantum circuits to investigate condensed matter systems consisting of strongly interacting particles,” adds Jarillo-Herrero.

This research was funded, in part, by the U.S. Army Research Office, the National Science Foundation, the U.S. Air Force Office of Scientific Research, and the U.S. Under Secretary of Defense for Research and Engineering.

A complementary study on magic-angle twisted trilayer graphene (MATTG), conducted by a collaboration between Philip Kim’s group at Harvard University and Jarillo-Herrero’s group at MIT appears in the same issue of Nature.

Eleven MIT faculty receive Presidential Early Career Awards

Eleven MIT faculty, including nine from the School of Engineering and two from the School of Science, were awarded the Presidential Early Career Award for Scientists and Engineers (PECASE). More than 15 additional MIT alumni were also honored. 

Established in 1996 by President Bill Clinton, the PECASE is awarded to scientists and engineers “who show exceptional potential for leadership early in their research careers.” The latest recipients were announced by the White House on Jan. 14 under President Joe Biden. Fourteen government agencies recommended researchers for the award.

The MIT faculty and alumni honorees are among 400 scientists and engineers recognized for innovation and scientific contributions. Those from the School of Engineering and School of Science who were honored are:

  • Tamara Broderick, associate professor in the Department of Electrical Engineering and Computer Science (EECS), was nominated by the Office of Naval Research for her project advancing “Lightweight representations for decentralized learning in data-rich environments.”
     
  • Michael James Carbin SM ’09, PhD ’15, associate professor in the Department of EECS, was nominated by the National Science Foundation (NSF) for his CAREER award, a project that developed techniques to execute programs reliably on approximate and unreliable computation substrates.
     
  • Christina Delimitrou, the KDD Career Development Professor in Communications and Technology and associate Professor in the Department of EECS, was nominated by the NSF for her group’s work on redesigning the cloud system stack given new cloud programming frameworks like microservices and serverless compute, as well as designing hardware acceleration techniques that make cloud data centers more predictable and resource-efficient.
     
  • Netta Engelhardt, the Biedenharn Career Development Associate Professor of Physics, was nominated by the Department of Energy for her research on the black hole information paradox and its implications for the fundamental quantum structure of space and time.
     
  • Robert Gilliard Jr., the Novartis Associate Professor of Chemistry, was selected based the results generated from his 2020 National Science Foundation CAREER award entitled: “CAREER: Boracycles with Unusual Bonding as Creative Strategies for Main-Group Functional Materials.”
     
  • Heather Janine Kulik PD ’09, PhD ’09, the Lammot du Pont Professor of Chemical Engineering, was nominated by the NSF for her 2019 proposal entitled “CAREER: Revealing spin-state-dependent reactivity in open-shell single atom catalysts with systematically-improvable computational tools.”
     
  • Nuno Loureiro, professor in the departments of Nuclear Science and Engineering and Physics, was nominated by the NSF for his work on the generation and amplification of magnetic fields in the universe.
     
  • Robert Macfarlane, associate professor in the Department of Materials Science and Engineering, was nominated by the Department of Defense (DoD)’s Air Force Office of Scientific Research. His research focuses on making new materials using molecular and nanoscale building blocks.
     
  • Ritu Raman, the Eugene Bell Career Development Professor of Tissue Engineering in the Department of Mechanical Engineering, was nominated by the DoD for her ARO-funded research that explored leveraging biological actuators in next-generation robots that can sense and adapt to their environments.
     
  • Ellen Roche, the Latham Family Career Development Professor and associate department head in the Department of Mechanical Engineering, was nominated by the NSF for her CAREER award, a project that aims to create a cutting-edge benchtop model combining soft robotics and organic tissue to accurately simulate the motions of the heart and diaphragm.
     
  • Justin Wilkerson, a visiting associate professor in the Department of Aeronautics and Astronautics, was nominated by the Air Force Office of Scientific Research (AFOSR) for his research primarily related to the design and optimization of novel multifunctional composite materials that can survive extreme environments.

Additional MIT alumni who were honored include: Elaheh Ahmadi ’20, MNG ’21; Ambika Bajpayee MNG ’07, PhD ’15; Katherine Bouman SM ’13, PhD ’17; Walter Cheng-Wan Lee ’95, MNG ’95, PhD ’05; Ismaila Dabo PhD ’08; Ying Diao SM ’10, PhD ’12; Eno Ebong ’99; Soheil Feizi- Khankandi SM ’10, PhD ’16; Mark Finlayson SM ’01, PhD ’12; Chelsea B. Finn ’14; Grace Xiang Gu SM ’14, PhD ’18; David Michael Isaacson PhD ’06, AF ’16; Lewei Lin ’05; Michelle Sander PhD ’12; Kevin Solomon SM ’08, PhD ’12; and Zhiting Tian PhD ’14.

Introducing the MIT Generative AI Impact Consortium

From crafting complex code to revolutionizing the hiring process, generative artificial intelligence is reshaping industries faster than ever before — pushing the boundaries of creativity, productivity, and collaboration across countless domains.

Enter the MIT Generative AI Impact Consortium, a collaboration between industry leaders and MIT’s top minds. As MIT President Sally Kornbluth highlighted last year, the Institute is poised to address the societal impacts of generative AI through bold collaborations. Building on this momentum and established through MIT’s Generative AI Week and impact papers, the consortium aims to harness AI’s transformative power for societal good, tackling challenges before they shape the future in unintended ways.

“Generative AI and large language models [LLMs] are reshaping everything, with applications stretching across diverse sectors,” says Anantha Chandrakasan, dean of the School of Engineering and MIT’s chief innovation and strategy officer, who leads the consortium. “As we push forward with newer and more efficient models, MIT is committed to guiding their development and impact on the world.”

Chandrakasan adds that the consortium’s vision is rooted in MIT’s core mission. “I am thrilled and honored to help advance one of President Kornbluth’s strategic priorities around artificial intelligence,” he says. “This initiative is uniquely MIT — it thrives on breaking down barriers, bringing together disciplines, and partnering with industry to create real, lasting impact. The collaborations ahead are something we’re truly excited about.”

Developing the blueprint for generative AI’s next leap

The consortium is guided by three pivotal questions, framed by Daniel Huttenlocher, dean of the MIT Schwarzman College of Computing and co-chair of the GenAI Dean’s oversight group, that go beyond AI’s technical capabilities and into its potential to transform industries and lives:

  1. How can AI-human collaboration create outcomes that neither could achieve alone?
  2. What is the dynamic between AI systems and human behavior, and how do we maximize the benefits while steering clear of risks?
  3. How can interdisciplinary research guide the development of better, safer AI technologies that improve human life?

Generative AI continues to advance at lightning speed, but its future depends on building a solid foundation. “Everybody recognizes that large language models will transform entire industries, but there’s no strong foundation yet around design principles,” says Tim Kraska, associate professor of electrical engineering and computer science in the MIT Computer Science and Artificial Intelligence Laboratory (CSAIL) and co-faculty director of the consortium.

“Now is a perfect time to look at the fundamentals — the building blocks that will make generative AI more effective and safer to use,” adds Kraska.

“What excites me is that this consortium isn’t just academic research for the distant future — we’re working on problems where our timelines align with industry needs, driving meaningful progress in real time,” says Vivek F. Farias, the Patrick J. McGovern (1959) Professor at the MIT Sloan School of Management, and co-faculty director of the consortium.

A “perfect match” of academia and industry

At the heart of the Generative AI Impact Consortium are six founding members: Analog Devices, The Coca-Cola Co., OpenAI, Tata Group, SK Telecom, and TWG Global. Together, they will work hand-in-hand with MIT researchers to accelerate breakthroughs and address industry-shaping problems.

The consortium taps into MIT’s expertise, working across schools and disciplines — led by MIT’s Office of Innovation and Strategy, in collaboration with the MIT Schwarzman College of Computing and all five of MIT’s schools.

“This initiative is the ideal bridge between academia and industry,” says Chandrakasan. “With companies spanning diverse sectors, the consortium brings together real-world challenges, data, and expertise. MIT researchers will dive into these problems to develop cutting-edge models and applications into these different domains.”

Industry partners: Collaborating on AI’s evolution

At the core of the consortium’s mission is collaboration — bringing MIT researchers and industry partners together to unlock generative AI’s potential while ensuring its benefits are felt across society.

Among the founding members is OpenAI, the creator of the generative AI chatbot ChatGPT.

“This type of collaboration between academics, practitioners, and labs is key to ensuring that generative AI evolves in ways that meaningfully benefit society,” says Anna Makanju, vice president of global impact at OpenAI, adding that OpenAI “is eager to work alongside MIT’s Generative AI Consortium to bridge the gap between cutting-edge AI research and the real-world expertise of diverse industries.”

The Coca-Cola Co. recognizes an opportunity to leverage AI innovation on a global scale. “We see a tremendous opportunity to innovate at the speed of AI and, leveraging The Coca-Cola Company’s global footprint, make these cutting-edge solutions accessible to everyone,” says Pratik Thakar, global vice president and head of generative AI. “Both MIT and The Coca-Cola Company are deeply committed to innovation, while also placing equal emphasis on the legally and ethically responsible development and use of technology.”

For TWG Global, the consortium offers the ideal environment to share knowledge and drive advancements. “The strength of the consortium is its unique combination of industry leaders and academia, which fosters the exchange of valuable lessons, technological advancements, and access to pioneering research,” says Drew Cukor, head of data and artificial intelligence transformation. Cukor adds that TWG Global “is keen to share its insights and actively engage with leading executives and academics to gain a broader perspective of how others are configuring and adopting AI, which is why we believe in the work of the consortium.”

The Tata Group views the collaboration as a platform to address some of AI’s most pressing challenges. “The consortium enables Tata to collaborate, share knowledge, and collectively shape the future of generative AI, particularly in addressing urgent challenges such as ethical considerations, data privacy, and algorithmic biases,” says Aparna Ganesh, vice president of Tata Sons Ltd.

Similarly, SK Telecom sees its involvement as a launchpad for growth and innovation. Suk-geun (SG) Chung, SK Telecom executive vice president and chief AI global officer, explains, “Joining the consortium presents a significant opportunity for SK Telecom to enhance its AI competitiveness in core business areas, including AI agents, AI semiconductors, data centers (AIDC), and physical AI,” says Chung. “By collaborating with MIT and leveraging the SK AI R&D Center as a technology control tower, we aim to forecast next-generation generative AI technology trends, propose innovative business models, and drive commercialization through academic-industrial collaboration.”

Alan Lee, chief technology officer of Analog Devices (ADI), highlights how the consortium bridges key knowledge gaps for both his company and the industry at large. “ADI can’t hire a world-leading expert in every single corner case, but the consortium will enable us to access top MIT researchers and get them involved in addressing problems we care about, as we also work together with others in the industry towards common goals,” he says.

The consortium will host interactive workshops and discussions to identify and prioritize challenges. “It’s going to be a two-way conversation, with the faculty coming together with industry partners, but also industry partners talking with each other,” says Georgia Perakis, the John C Head III Dean (Interim) of the MIT Sloan School of Management and professor of operations management, operations research and statistics, who serves alongside Huttenlocher as co-chair of the GenAI Dean’s oversight group.

Preparing for the AI-enabled workforce of the future

With AI poised to disrupt industries and create new opportunities, one of the consortium’s core goals is to guide that change in a way that benefits both businesses and society.

“When the first commercial digital computers were introduced [the UNIVAC was delivered to the U.S. Census Bureau in 1951], people were worried about losing their jobs,” says Kraska. “And yes, jobs like large-scale, manual data entry clerks and human ‘computers,’ people tasked with doing manual calculations, largely disappeared over time. But the people impacted by those first computers were trained to do other jobs.”

The consortium aims to play a key role in preparing the workforce of tomorrow by educating global business leaders and employees on generative AI evolving uses and applications. With the pace of innovation accelerating, leaders face a flood of information and uncertainty.

“When it comes to educating leaders about generative AI, it’s about helping them navigate the complexity of the space right now, because there’s so much hype and hundreds of papers published daily,” says Kraska. “The hard part is understanding which developments could actually have a chance of changing the field and which are just tiny improvements. There’s a kind of FOMO [fear of missing out] for leaders that we can help reduce.”

Defining success: Shared goals for generative AI impact

Success within the initiative is defined by shared progress, open innovation, and mutual growth. “Consortium participants recognize, I think, that when I share my ideas with you, and you share your ideas with me, we’re both fundamentally better off,” explains Farias. “Progress on generative AI is not zero-sum, so it makes sense for this to be an open-source initiative.”

While participants may approach success from different angles, they share a common goal of advancing generative AI for broad societal benefit. “There will be many success metrics,” says Perakis. “We’ll educate students, who will be networking with companies. Companies will come together and learn from each other. Business leaders will come to MIT and have discussions that will help all of us, not just the leaders themselves.”

For Analog Devices’ Alan Lee, success is measured in tangible improvements that drive efficiency and product innovation: “For us at ADI, it’s a better, faster quality of experience for our customers, and that could mean better products. It could mean faster design cycles, faster verification cycles, and faster tuning of equipment that we already have or that we’re going to develop for the future. But beyond that, we want to help the world be a better, more efficient place.”

Ganesh highlights success through the lens of real-world application. “Success will also be defined by accelerating AI adoption within Tata companies, generating actionable knowledge that can be applied in real-world scenarios, and delivering significant advantages to our customers and stakeholders,” she says.

Generative AI is no longer confined to isolated research labs — it’s driving innovation across industries and disciplines. At MIT, the technology has become a campus-wide priority, connecting researchers, students, and industry leaders to solve complex challenges and uncover new opportunities. “It’s truly an MIT initiative,” says Farias, “one that’s much larger than any individual or department on campus.”

Aligning AI with human values

Senior Audrey Lorvo is researching AI safety, which seeks to ensure increasingly intelligent AI models are reliable and can benefit humanity. The growing field focuses on technical challenges like robustness and AI alignment with human values, as well as societal concerns like transparency and accountability. Practitioners are also concerned with the potential existential risks associated with increasingly powerful AI tools.

“Ensuring AI isn’t misused or acts contrary to our intentions is increasingly important as we approach artificial general intelligence (AGI),” says Lorvo, a computer science, economics, and data science major. AGI describes the potential of artificial intelligence to match or surpass human cognitive capabilities.

An MIT Schwarzman College of Computing Social and Ethical Responsibilities of Computing (SERC) scholar, Lorvo looks closely at how AI might automate AI research and development processes and practices. A member of the Big Data research group, she’s investigating the social and economic implications associated with AI’s potential to accelerate research on itself and how to effectively communicate these ideas and potential impacts to general audiences including legislators, strategic advisors, and others.

Lorvo emphasizes the need to critically assess AI’s rapid advancements and their implications, ensuring organizations have proper frameworks and strategies in place to address risks. “We need to both ensure humans reap AI’s benefits and that we don’t lose control of the technology,” she says. “We need to do all we can to develop it safely.”

Her participation in efforts like the AI Safety Technical Fellowship reflect her investment in understanding the technical aspects of AI safety. The fellowship provides opportunities to review existing research on aligning AI development with considerations of potential human impact. “The fellowship helped me understand AI safety’s technical questions and challenges so I can potentially propose better AI governance strategies,” she says. According to Lorvo, companies on AI’s frontier continue to push boundaries, which means we’ll need to implement effective policies that prioritize human safety without impeding research.

Value from human engagement

When arriving at MIT, Lorvo knew she wanted to pursue a course of study that would allow her to work at the intersection of science and the humanities. The variety of offerings at the Institute made her choices difficult, however.

“There are so many ways to help advance the quality of life for individuals and communities,” she says, “and MIT offers so many different paths for investigation.”

Beginning with economics — a discipline she enjoys because of its focus on quantifying impact — Lorvo investigated math, political science, and urban planning before choosing Course 6-14.

“Professor Joshua Angrist’s econometrics classes helped me see the value in focusing on economics, while the data science and computer science elements appealed to me because of the growing reach and potential impact of AI,” she says. “We can use these tools to tackle some of the world’s most pressing problems and hopefully overcome serious challenges.”

Lorvo has also pursued concentrations in urban studies and planning and international development.

As she’s narrowed her focus, Lorvo finds she shares an outlook on humanity with other members of the MIT community like the MIT AI Alignment group, from whom she learned quite a bit about AI safety. “Students care about their marginal impact,” she says.

Marginal impact, the additional effect of a specific investment of time, money, or effort, is a way to measure how much a contribution adds to what is already being done, rather than focusing on the total impact. This can potentially influence where people choose to devote their resources, an idea that appeals to Lorvo.

“In a world of limited resources, a data-driven approach to solving some of our biggest challenges can benefit from a tailored approach that directs people to where they’re likely to do the most good,” she says. “If you want to maximize your social impact, reflecting on your career choice’s marginal impact can be very valuable.”

Lorvo also values MIT’s focus on educating the whole student and has taken advantage of opportunities to investigate disciplines like philosophy through MIT Concourse, a program that facilitates dialogue between science and the humanities. Concourse hopes participants gain guidance, clarity, and purpose for scientific, technical, and human pursuits.

Student experiences at the Institute

Lorvo invests her time outside the classroom in creating memorable experiences and fostering relationships with her classmates. “I’m fortunate that there’s space to balance my coursework, research, and club commitments with other activities, like weightlifting and off-campus initiatives,” she says. “There are always so many clubs and events available across the Institute.”

These opportunities to expand her worldview have challenged her beliefs and exposed her to new interest areas that have altered her life and career choices for the better. Lorvo, who is fluent in French, English, Spanish, and Portuguese, also applauds MIT for the international experiences it provides for students.

“I’ve interned in Santiago de Chile and Paris with MISTI and helped test a water vapor condensing chamber that we designed in a fall 2023 D-Lab class in collaboration with the Madagascar Polytechnic School and Tatirano NGO [nongovernmental organization],” she says, “and have enjoyed the opportunities to learn about addressing economic inequality through my International Development and D-Lab classes.”

As president of MIT’s Undergraduate Economics Association, Lorvo connects with other students interested in economics while continuing to expand her understanding of the field. She enjoys the relationships she’s building while also participating in the association’s events throughout the year. “Even as a senior, I’ve found new campus communities to explore and appreciate,” she says. “I encourage other students to continue exploring groups and classes that spark their interests throughout their time at MIT.”

After graduation, Lorvo wants to continue investigating AI safety and researching governance strategies that can help ensure AI’s safe and effective deployment.

“Good governance is essential to AI’s successful development and ensuring humanity can benefit from its transformative potential,” she says. “We must continue to monitor AI’s growth and capabilities as the technology continues to evolve.”

Understanding technology’s potential impacts on humanity, doing good, continually improving, and creating spaces where big ideas can see the light of day continue to drive Lorvo. Merging the humanities with the sciences animates much of what she does. “I always hoped to contribute to improving people’s lives, and AI represents humanity’s greatest challenge and opportunity yet,” she says. “I believe the AI safety field can benefit from people with interdisciplinary experiences like the kind I’ve been fortunate to gain, and I encourage anyone passionate about shaping the future to explore it.”

User-friendly system can help developers build more efficient simulations and AI models

The neural network artificial intelligence models used in applications like medical image processing and speech recognition perform operations on hugely complex data structures that require an enormous amount of computation to process. This is one reason deep-learning models consume so much energy.

To improve the efficiency of AI models, MIT researchers created an automated system that enables developers of deep learning algorithms to simultaneously take advantage of two types of data redundancy. This reduces the amount of computation, bandwidth, and memory storage needed for machine learning operations.

Existing techniques for optimizing algorithms can be cumbersome and typically only allow developers to capitalize on either sparsity or symmetry — two different types of redundancy that exist in deep learning data structures.

By enabling a developer to build an algorithm from scratch that takes advantage of both redundancies at once, the MIT researchers’ approach boosted the speed of computations by nearly 30 times in some experiments.

Because the system utilizes a user-friendly programming language, it could optimize machine-learning algorithms for a wide range of applications. The system could also help scientists who are not experts in deep learning but want to improve the efficiency of AI algorithms they use to process data. In addition, the system could have applications in scientific computing.

“For a long time, capturing these data redundancies has required a lot of implementation effort. Instead, a scientist can tell our system what they would like to compute in a more abstract way, without telling the system exactly how to compute it,” says Willow Ahrens, an MIT postdoc and co-author of a paper on the system, which will be presented at the International Symposium on Code Generation and Optimization.

She is joined on the paper by lead author Radha Patel ’23, SM ’24 and senior author Saman Amarasinghe, a professor in the Department of Electrical Engineering and Computer Science (EECS) and a principal researcher in the Computer Science and Artificial Intelligence Laboratory (CSAIL).

Cutting out computation

In machine learning, data are often represented and manipulated as multidimensional arrays known as tensors. A tensor is like a matrix, which is a rectangular array of values arranged on two axes, rows and columns. But unlike a two-dimensional matrix, a tensor can have many dimensions, or axes, making tensors more difficult to manipulate.

Deep-learning models perform operations on tensors using repeated matrix multiplication and addition — this process is how neural networks learn complex patterns in data. The sheer volume of calculations that must be performed on these multidimensional data structures requires an enormous amount of computation and energy.

But because of the way data in tensors are arranged, engineers can often boost the speed of a neural network by cutting out redundant computations.

For instance, if a tensor represents user review data from an e-commerce site, since not every user reviewed every product, most values in that tensor are likely zero. This type of data redundancy is called sparsity. A model can save time and computation by only storing and operating on non-zero values.

In addition, sometimes a tensor is symmetric, which means the top half and bottom half of the data structure are equal. In this case, the model only needs to operate on one half, reducing the amount of computation. This type of data redundancy is called symmetry.

“But when you try to capture both of these optimizations, the situation becomes quite complex,” Ahrens says.

To simplify the process, she and her collaborators built a new compiler, which is a computer program that translates complex code into a simpler language that can be processed by a machine. Their compiler, called SySTeC, can optimize computations by automatically taking advantage of both sparsity and symmetry in tensors.

They began the process of building SySTeC by identifying three key optimizations they can perform using symmetry.

First, if the algorithm’s output tensor is symmetric, then it only needs to compute one half of it. Second, if the input tensor is symmetric, then algorithm only needs to read one half of it. Finally, if intermediate results of tensor operations are symmetric, the algorithm can skip redundant computations.

Simultaneous optimizations

To use SySTeC, a developer inputs their program and the system automatically optimizes their code for all three types of symmetry. Then the second phase of SySTeC performs additional transformations to only store non-zero data values, optimizing the program for sparsity.

In the end, SySTeC generates ready-to-use code.

“In this way, we get the benefits of both optimizations. And the interesting thing about symmetry is, as your tensor has more dimensions, you can get even more savings on computation,” Ahrens says.

The researchers demonstrated speedups of nearly a factor of 30 with code generated automatically by SySTeC.

Because the system is automated, it could be especially useful in situations where a scientist wants to process data using an algorithm they are writing from scratch.

In the future, the researchers want to integrate SySTeC into existing sparse tensor compiler systems to create a seamless interface for users. In addition, they would like to use it to optimize code for more complicated programs.

This work is funded, in part, by Intel, the National Science Foundation, the Defense Advanced Research Projects Agency, and the Department of Energy.

“Forever grateful for MIT Open Learning for making knowledge accessible and fostering a network of curious minds”

Bia Adams, a London-based neuropsychologist, former professional ballet dancer, and MIT Open Learning learner, has built her career across decades of diverse, interconnected experiences and an emphasis on lifelong learning. She earned her bachelor’s degree in clinical and behavioral psychology, and then worked as a psychologist and therapist for several years before taking a sabbatical in her late 20s to study at the London Contemporary Dance School and The Royal Ballet — fulfilling a long-time dream.

“In hindsight, I think what drew me most to ballet was not so much the form itself,” says Adams, “but more of a subconscious desire to make sense of my body moving through space and time, my emotions and motivations — all within a discipline that is rigorous, meticulous, and routine-based. It’s an endeavor to make sense of the world and myself.”

After acquiring some dance-related injuries, Adams returned to psychology. She completed an online certificate program specializing in medical neuroscience via Duke University, focusing on how pathology arises out of the way the brain computes information and generates behavior.

In addition to her clinical practice, she has also worked at a data science and AI consultancy for neural network research.

In 2022, in search of new things to learn and apply to both her work and personal life, Adams discovered MIT OpenCourseWare within MIT Open Learning. She was drawn to class 8.04 (Quantum Physics I), which specifically focuses on quantum mechanics, as she was hoping to finally gain some understanding of complex topics that she had tried to teach herself in the past with limited success. She credits the course’s lectures, taught by Allan Adams (physicist and principal investigator of the MIT Future Ocean Lab), with finally making these challenging topics approachable.

“I still talk to my friends at length about exciting moments in these lectures,” says Adams. “After the first class, I was hooked.”

Adams’s journey through MIT Open Learning’s educational resources quickly led to a deeper interest in computational neuroscience. She learned how to use tools from mathematics and computer science to better understand the brain, nervous system, and behavior.

She says she gained many new insights from class 6.034 (Artificial Intelligence), particularly in watching the late Professor Patrick Winston’s lectures. She appreciated learning more about the cognitive psychology aspect of AI, including how pioneers in the field looked at how the brain processes information and aimed to build programs that could solve problems. She further enhanced her understanding of AI with the Minds and Machines course on MITx Online, part of Open Learning.

Adams is now in the process of completing Introduction to Computer Science and Programming Using Python, taught by John Guttag; Eric Grimson, former interim vice president for Open Learning; and Ana Bell.

“I am multilingual, and I think the way my brain processes code is similar to the way computers code,” says Adams. “I find learning to code similar to learning a foreign language: both exhilarating and intimidating. Learning the rules, deciphering the syntax, and building my own world through code is one of the most fascinating challenges of my life.”

Adams is also pursuing a master’s degree at Duke and the University College of London, focusing on the neurobiology of sleep and looking particularly at how the biochemistry of the brain can affect this critical function. As a complement to this research, she is currently exploring class 9.40 (Introduction to Neural Computation), taught by Michale Fee and Daniel Zysman, which introduces quantitative approaches to understanding brain and cognitive functions and neurons and covers foundational quantitative tools of data analysis in neuroscience.

In addition to the courses related more directly to her field, MIT Open Learning also provided Adams an opportunity to explore other academic areas. She delved into philosophy for the first time, taking Paradox and Infinity, taught by Professor Agustín Rayo, the Kenan Sahin Dean of the MIT School of Humanities, Arts, and Social Sciences, and Digital Learning Lab Fellow David Balcarras, which looks at the intersection of philosophy and mathematics. She also was able to explore in more depth immunology, which had always been of great interest to her, through Professor Adam Martin’s lectures on this topic in class 7.016 (Introductory Biology).

“I am forever grateful for MIT Open Learning,” says Adams, “for making knowledge accessible and fostering a network of curious minds, all striving to share, expand, and apply this knowledge for the greater good.”

Toward video generative models of the molecular world

As the capabilities of generative AI models have grown, you’ve probably seen how they can transform simple text prompts into hyperrealistic images and even extended video clips.

More recently, generative AI has shown potential in helping chemists and biologists explore static molecules, like proteins and DNA. Models like AlphaFold can predict molecular structures to accelerate drug discovery, and the MIT-assisted “RFdiffusion,” for example, can help design new proteins. One challenge, though, is that molecules are constantly moving and jiggling, which is important to model when constructing new proteins and drugs. Simulating these motions on a computer using physics — a technique known as molecular dynamics — can be very expensive, requiring billions of time steps on supercomputers.

As a step toward simulating these behaviors more efficiently, MIT Computer Science and Artificial Intelligence Laboratory (CSAIL) and Department of Mathematics researchers have developed a generative model that learns from prior data. The team’s system, called MDGen, can take a frame of a 3D molecule and simulate what will happen next like a video, connect separate stills, and even fill in missing frames. By hitting the “play button” on molecules, the tool could potentially help chemists design new molecules and closely study how well their drug prototypes for cancer and other diseases would interact with the molecular structure it intends to impact.

Co-lead author Bowen Jing SM ’22 says that MDGen is an early proof of concept, but it suggests the beginning of an exciting new research direction. “Early on, generative AI models produced somewhat simple videos, like a person blinking or a dog wagging its tail,” says Jing, a PhD student at CSAIL. “Fast forward a few years, and now we have amazing models like Sora or Veo that can be useful in all sorts of interesting ways. We hope to instill a similar vision for the molecular world, where dynamics trajectories are the videos. For example, you can give the model the first and 10th frame, and it’ll animate what’s in between, or it can remove noise from a molecular video and guess what was hidden.”

The researchers say that MDGen represents a paradigm shift from previous comparable works with generative AI in a way that enables much broader use cases. Previous approaches were “autoregressive,” meaning they relied on the previous still frame to build the next, starting from the very first frame to create a video sequence. In contrast, MDGen generates the frames in parallel with diffusion. This means MDGen can be used to, for example, connect frames at the endpoints, or “upsample” a low frame-rate trajectory in addition to pressing play on the initial frame.

This work was presented in a paper shown at the Conference on Neural Information Processing Systems (NeurIPS) this past December. Last summer, it was awarded for its potential commercial impact at the International Conference on Machine Learning’s ML4LMS Workshop.

Some small steps forward for molecular dynamics

In experiments, Jing and his colleagues found that MDGen’s simulations were similar to running the physical simulations directly, while producing trajectories 10 to 100 times faster.

The team first tested their model’s ability to take in a 3D frame of a molecule and generate the next 100 nanoseconds. Their system pieced together successive 10-nanosecond blocks for these generations to reach that duration. The team found that MDGen was able to compete with the accuracy of a baseline model, while completing the video generation process in roughly a minute — a mere fraction of the three hours that it took the baseline model to simulate the same dynamic.

When given the first and last frame of a one-nanosecond sequence, MDGen also modeled the steps in between. The researchers’ system demonstrated a degree of realism in over 100,000 different predictions: It simulated more likely molecular trajectories than its baselines on clips shorter than 100 nanoseconds. In these tests, MDGen also indicated an ability to generalize on peptides it hadn’t seen before.

MDGen’s capabilities also include simulating frames within frames, “upsampling” the steps between each nanosecond to capture faster molecular phenomena more adequately. It can even ​​“inpaint” structures of molecules, restoring information about them that was removed. These features could eventually be used by researchers to design proteins based on a specification of how different parts of the molecule should move.

Toying around with protein dynamics

Jing and co-lead author Hannes Stärk say that MDGen is an early sign of progress toward generating molecular dynamics more efficiently. Still, they lack the data to make these models immediately impactful in designing drugs or molecules that induce the movements chemists will want to see in a target structure.

The researchers aim to scale MDGen from modeling molecules to predicting how proteins will change over time. “Currently, we’re using toy systems,” says Stärk, also a PhD student at CSAIL. “To enhance MDGen’s predictive capabilities to model proteins, we’ll need to build on the current architecture and data available. We don’t have a YouTube-scale repository for those types of simulations yet, so we’re hoping to develop a separate machine-learning method that can speed up the data collection process for our model.”

For now, MDGen presents an encouraging path forward in modeling molecular changes invisible to the naked eye. Chemists could also use these simulations to delve deeper into the behavior of medicine prototypes for diseases like cancer or tuberculosis.

“Machine learning methods that learn from physical simulation represent a burgeoning new frontier in AI for science,” says Bonnie Berger, MIT Simons Professor of Mathematics, CSAIL principal investigator, and senior author on the paper. “MDGen is a versatile, multipurpose modeling framework that connects these two domains, and we’re very excited to share our early models in this direction.”

“Sampling realistic transition paths between molecular states is a major challenge,” says fellow senior author Tommi Jaakkola, who is the MIT Thomas Siebel Professor of electrical engineering and computer science and the Institute for Data, Systems, and Society, and a CSAIL principal investigator. “This early work shows how we might begin to address such challenges by shifting generative modeling to full simulation runs.”

Researchers across the field of bioinformatics have heralded this system for its ability to simulate molecular transformations. “MDGen models molecular dynamics simulations as a joint distribution of structural embeddings, capturing molecular movements between discrete time steps,” says Chalmers University of Technology associate professor Simon Olsson, who wasn’t involved in the research. “Leveraging a masked learning objective, MDGen enables innovative use cases such as transition path sampling, drawing analogies to inpainting trajectories connecting metastable phases.”

The researchers’ work on MDGen was supported, in part, by the National Institute of General Medical Sciences, the U.S. Department of Energy, the National Science Foundation, the Machine Learning for Pharmaceutical Discovery and Synthesis Consortium, the Abdul Latif Jameel Clinic for Machine Learning in Health, the Defense Threat Reduction Agency, and the Defense Advanced Research Projects Agency.