2024-25 EECS Faculty Award Roundup

This ongoing listing of awards and recognitions won by our faculty is added to all year, beginning in September.

Tamara Broderick, Associate Professor of EECS, was named a recipient of the Presidential Early Career Award for Scientists and Engineers (PECASE).

Tamara Broderick, Associate Professor of EECS, received the 2025 Burgess (1952) & Elizabeth Jamieson Prize for Excellence in Teaching at MIT.

Regina Barzilay, School of Engineering Distinguished Professor for AI and Health, was awarded the 2025 IEEE Frances E. Allen Medal.

Regina Barzilay, School of Engineering Distinguished Professor for AI and Health, was named to the Time 100AI list.

Sara Beery, Assistant Professor, was named to the cohort of 2024 AI2050 Early Career Fellows by Schmidt Sciences.

Sara Beery, Assistant Professor, was awarded the NSF CAREER Award.

Rodney Brooks, Panasonic Professor of Robotics (Emeritus), was elected to the National Academy of Sciences.

Michael Carbin, Associate Professor, was named a recipient of the Presidential Early Career Award for Scientists and Engineers (PECASE).

Henry Corrigan-Gibbs, Assistant Professor, has received the 2025 Junior Bose Award.

Henry Corrigan-Gibbs, Assistant Professor, has received the 2025 Google ML and Systems Junior Faculty Award.

Christina Delimitrou, Associate Professor, has received the 2025 Google ML and Systems Junior Faculty Award.

Christina Delimitrou, Associate Professor, was named a recipient of the Presidential Early Career Award for Scientists and Engineers (PECASE).

Priya Donti, Assistant Professor, was named to the Time 100AI 2025 list.

Gabriele Farina, Assistant Professor, was named to the cohort of 2024 AI2050 Early Career Fellows by Schmidt Sciences.

James Fujimoto, the Elihu Thomson Professor in Electrical Engineering, was awarded the Honda Prize 2024 by the Honda Foundation.

James Fujimoto, the Elihu Thomson Professor in Electrical Engineering, was named a 2025 inductee into the National Inventors Hall of Fame.

Mohsen Ghaffari, Associate Professor, was named to the cohort of 2024 AI2050 Early Career Fellows by Schmidt Sciences.

Marzyeh Ghassemi, Associate Professor, was named to the cohort of 2024 AI2050 Early Career Fellows by Schmidt Sciences.

Marzyeh Ghassemi, Associate Professor, was named to the cohort of 2025 Sloan Research Fellows.

Dina Katabi, the Thuan (1990) and Nicole Pham Professor, received the 2026 IEEE Koji Kobayashi Computers and Communications Award.

Yoon Kim, Assistant Professor, was named to the cohort of 2024 AI2050 Early Career Fellows by Schmidt Sciences.

Yoon Kim, Assistant Professor, has received the 2025 Google ML and Systems Junior Faculty Award.

Jing Kong, the Jerry McAfee (1940) Professor In Engineering, was awarded the MIT Postdoctoral Association’s Award for Excellence in Postdoctoral Mentoring. 

Steve Leeb, the Emanuel E. Landsman (1958) Professor, received the 2025 IEEE Sensors Journal Best Paper Award, along with coauthors Daniel Monagle and Eric A. Ponce, for the paper entitled “Rule the Joule: An Energy Management Design Guide for Self-Powered Sensors”. 

Paul Liang, Assistant Professor, was named one of the Forbes 30 Under 30 in the Science category for 2025.

Laura Lewis, the Athinoula A. Martinos Associate Professor in the Institute for Mechanical Engineering and Science and EECS, was awarded the MIT Postdoctoral Association’s Award for Excellence in Postdoctoral Mentoring. 

Kuikui Liu, Elting Morison Career Development Professor and Assistant Professor, was awarded the 2025 Michael and Sheila Held Prize by the National Academy of Sciences.

Tomás Lozano-Pérez, School of Engineering Professor of Teaching Excellence, was elected to the National Academy of Engineering.

Farnaz Niroui, Associate Professor, was named a recipient of the DARPA Director’s Fellowship Award.

Jelena Notaros, Robert J. Shillman (1974) Career Development Professor in Electrical Engineering and Computer Science, was named one of the Forbes 30 Under 30 All-Star Alumni in the Science category for 2025.

Jelena Notaros, Robert J. Shillman (1974) Career Development Professor in Electrical Engineering and Computer Science, was awarded the 2025 Ruth and Joel Spira Award for Excellence in Teaching by MIT’s School of Engineering.

William Oliver, Associate Director, RLE; Henry Ellis Warren (1894) Professor, was named a Fellow of the IEEE.

Anthony Pennes, Technical Instructor, was awarded the 2025 Teaching with Digital Technology Award.

Jonathan Ragan-Kelley, Associate Professor, was awarded the 2025 Ruth and Joel Spira Award for Excellence in Teaching by MIT’s School of Engineering.

Martin Rinard, Professor of CS and Engineering, was awarded the 2025 SIGSOFT Outstanding Research Award.

Daniela Rus, Andrew (1956) and Erna Viterbi Professor of Electrical Engineering and Computer Science, was awarded the 2025 IEEE Edison Medal.

Daniela Rus, Andrew (1956) and Erna Viterbi Professor of Electrical Engineering and Computer Science, was recently named a co-recipient of the 2024 John Scott Award by the board of directors of City Trusts. 

Daniela Rus, Andrew (1956) and Erna Viterbi Professor of Electrical Engineering and Computer Science, was recently named a foreign member of the French national academy of medicine, or Académie Nationale de Médecine (ANM).

Shen Shen, Lecturer, was awarded the 2025 Teaching with Digital Technology Award.

Henry “Hank” Smith, Joseph F. and Nancy P. Keithley Professor of EE (Emeritus), received the SPIE Frits Zernike Award for Microlithography from the International society for Optics and Photonics (SPIE).

Justin Solomon, Associate Professor of EECS, received the 2025 Burgess (1952) & Elizabeth Jamieson Prize for Excellence in Teaching at MIT.

Joe Steinmeyer, Senior Lecturer, was awarded the Distinguished Educator Award by MIT’s School of Engineering.

Sixian You, Alfred Henry (1929) and Jean Morrison Hayes Career Development Professor; Assistant Professor, along with an interdisciplinary research team, was award the 2025 J-WAFS Grand Challenge Grant.

AI pareidolia: Can machines spot faces in inanimate objects?

In 1994, Florida jewelry designer Diana Duyser discovered what she believed to be the Virgin Mary’s image in a grilled cheese sandwich, which she preserved and later auctioned for $28,000. But how much do we really understand about pareidolia, the phenomenon of seeing faces and patterns in objects when they aren’t really there? 

A new study from the MIT Computer Science and Artificial Intelligence Laboratory (CSAIL) delves into this phenomenon, introducing an extensive, human-labeled dataset of 5,000 pareidolic images, far surpassing previous collections. Using this dataset, the team discovered several surprising results about the differences between human and machine perception, and how the ability to see faces in a slice of toast might have saved your distant relatives’ lives.

“Face pareidolia has long fascinated psychologists, but it’s been largely unexplored in the computer vision community,” says Mark Hamilton, MIT PhD student in electrical engineering and computer science, CSAIL affiliate, and lead researcher on the work. “We wanted to create a resource that could help us understand how both humans and AI systems process these illusory faces.”

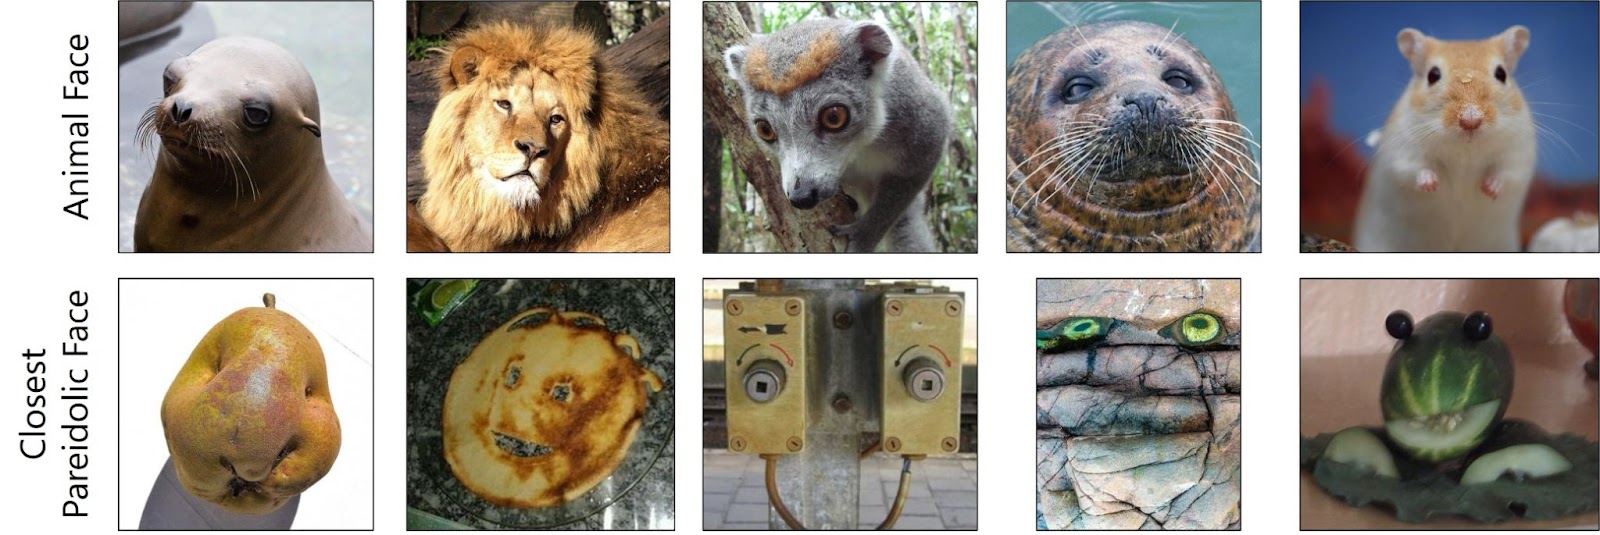
So what did all of these fake faces reveal? For one, AI models don’t seem to recognize pareidolic faces like we do. Surprisingly, the team found that it wasn’t until they trained algorithms to recognize animal faces that they became significantly better at detecting pareidolic faces. This unexpected connection hints at a possible evolutionary link between our ability to spot animal faces — crucial for survival — and our tendency to see faces in inanimate objects. “A result like this seems to suggest that pareidolia might not arise from human social behavior, but from something deeper: like quickly spotting a lurking tiger, or identifying which way a deer is looking so our primordial ancestors could hunt,” says Hamilton.

A row of five photos of animal faces atop five photos of inanimate objects that look like faces

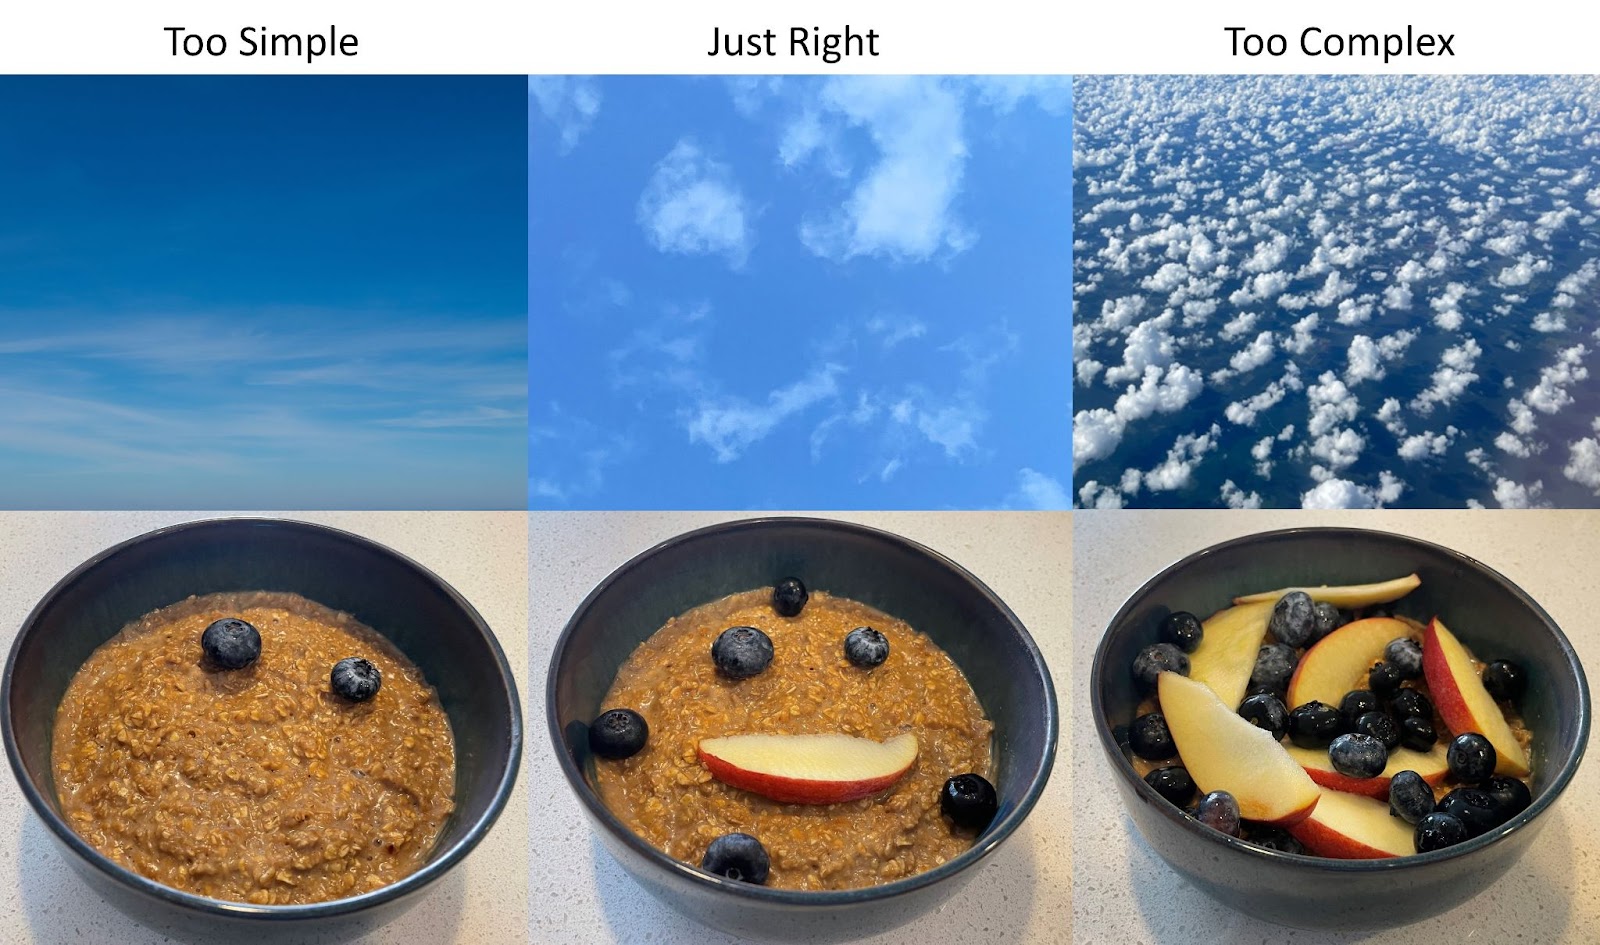
Another intriguing discovery is what the researchers call the “Goldilocks Zone of Pareidolia,” a class of images where pareidolia is most likely to occur. “There’s a specific range of visual complexity where both humans and machines are most likely to perceive faces in non-face objects,” William T. Freeman, MIT professor of electrical engineering and computer science and principal investigator of the project says. “Too simple, and there’s not enough detail to form a face. Too complex, and it becomes visual noise.”

To uncover this, the team developed an equation that models how people and algorithms detect illusory faces.  When analyzing this equation, they found a clear “pareidolic peak” where the likelihood of seeing faces is highest, corresponding to images that have “just the right amount” of complexity. This predicted “Goldilocks zone” was then validated in tests with both real human subjects and AI face detection systems.

3 photos of clouds above 3 photos of a fruit tart. The left photo of each is “Too Simple” to perceive a face; the middle photo is “Just Right,” and the last photo is “Too Complex"

This new dataset, “Faces in Things,” dwarfs those of previous studies that typically used only 20-30 stimuli. This scale allowed the researchers to explore how state-of-the-art face detection algorithms behaved after fine-tuning on pareidolic faces, showing that not only could these algorithms be edited to detect these faces, but that they could also act as a silicon stand-in for our own brain, allowing the team to ask and answer questions about the origins of pareidolic face detection that are impossible to ask in humans. 

To build this dataset, the team curated approximately 20,000 candidate images from the LAION-5B dataset, which were then meticulously labeled and judged by human annotators. This process involved drawing bounding boxes around perceived faces and answering detailed questions about each face, such as the perceived emotion, age, and whether the face was accidental or intentional. “Gathering and annotating thousands of images was a monumental task,” says Hamilton. “Much of the dataset owes its existence to my mom,” a retired banker, “who spent countless hours lovingly labeling images for our analysis.”

The study also has potential applications in improving face detection systems by reducing false positives, which could have implications for fields like self-driving cars, human-computer interaction, and robotics. The dataset and models could also help areas like product design, where understanding and controlling pareidolia could create better products. “Imagine being able to automatically tweak the design of a car or a child’s toy so it looks friendlier, or ensuring a medical device doesn’t inadvertently appear threatening,” says Hamilton.

“It’s fascinating how humans instinctively interpret inanimate objects with human-like traits. For instance, when you glance at an electrical socket, you might immediately envision it singing, and you can even imagine how it would ‘move its lips.’ Algorithms, however, don’t naturally recognize these cartoonish faces in the same way we do,” says Hamilton. “This raises intriguing questions: What accounts for this difference between human perception and algorithmic interpretation? Is pareidolia beneficial or detrimental? Why don’t algorithms experience this effect as we do? These questions sparked our investigation, as this classic psychological phenomenon in humans had not been thoroughly explored in algorithms.”

As the researchers prepare to share their dataset with the scientific community, they’re already looking ahead. Future work may involve training vision-language models to understand and describe pareidolic faces, potentially leading to AI systems that can engage with visual stimuli in more human-like ways.

“This is a delightful paper! It is fun to read and it makes me think. Hamilton et al. propose a tantalizing question: Why do we see faces in things?” says Pietro Perona, the Allen E. Puckett Professor of Electrical Engineering at Caltech, who was not involved in the work. “As they point out, learning from examples, including animal faces, goes only half-way to explaining the phenomenon. I bet that thinking about this question will teach us something important about how our visual system generalizes beyond the training it receives through life.”

Hamilton and Freeman’s co-authors include Simon Stent, staff research scientist at the Toyota Research Institute; Ruth Rosenholtz, principal research scientist in the Department of Brain and Cognitive Sciences, NVIDIA research scientist, and former CSAIL member; and CSAIL affiliates postdoc Vasha DuTell, Anne Harrington MEng ’23, and Research Scientist Jennifer Corbett. Their work was supported, in part, by the National Science Foundation and the CSAIL MEnTorEd Opportunities in Research (METEOR) Fellowship, while being sponsored by the United States Air Force Research Laboratory and the United States Air Force Artificial Intelligence Accelerator. The MIT SuperCloud and Lincoln Laboratory Supercomputing Center provided HPC resources for the researchers’ results.

This work is being presented this week at the European Conference on Computer Vision.

Enhancing LLM collaboration for smarter, more efficient solutions

Ever been asked a question you only knew part of the answer to? To give a more informed response, your best move would be to phone a friend with more knowledge on the subject.

This collaborative process can also help large language models (LLMs) improve their accuracy. Still, it’s been difficult to teach LLMs to recognize when they should collaborate with another model on an answer. Instead of using complex formulas or large amounts of labeled data to spell out where models should work together, researchers at MIT’s Computer Science and Artificial Intelligence Laboratory (CSAIL) have envisioned a more organic approach.

Their new algorithm, called “Co-LLM,” can pair a general-purpose base LLM with a more specialized model and help them work together. As the former crafts an answer, Co-LLM reviews each word (or token) within its response to see where it can call upon a more accurate answer from the expert model. This process leads to more accurate replies to things like medical prompts and math and reasoning problems. Since the expert model is not needed at each iteration, this also leads to more efficient response generation.

To decide when a base model needs help from an expert model, the framework uses machine learning to train a “switch variable,” or a tool that can indicate the competence of each word within the two LLMs’ responses. The switch is like a project manager, finding areas where it should call in a specialist. If you asked Co-LLM to name some examples of extinct bear species, for instance, two models would draft answers together. The general-purpose LLM begins to put together a reply, with the switch variable intervening at the parts where it can slot in a better token from the expert model, such as adding the year when the bear species became extinct.

“With Co-LLM, we’re essentially training a general-purpose LLM to ‘phone’ an expert model when needed,” says Shannon Shen, an MIT PhD student in electrical engineering and computer science and CSAIL affiliate who’s a lead author on a new paper about the approach. “We use domain-specific data to teach the base model about its counterpart’s expertise in areas like biomedical tasks and math and reasoning questions. This process automatically finds the parts of the data that are hard for the base model to generate, and then it instructs the base model to switch to the expert LLM, which was pretrained on data from a similar field. The general-purpose model provides the ‘scaffolding’ generation, and when it calls on the specialized LLM, it prompts the expert to generate the desired tokens. Our findings indicate that the LLMs learn patterns of collaboration organically, resembling how humans recognize when to call upon an expert to fill in the blanks.”

A combination of flexibility and factuality

Imagine asking a general-purpose LLM to name the ingredients of a specific prescription drug. It may reply incorrectly, necessitating the expertise of a specialized model.

To showcase Co-LLM’s flexibility, the researchers used data like the BioASQ medical set to couple a base LLM with expert LLMs in different domains, like the Meditron model, which is pretrained on unlabeled medical data. This enabled the algorithm to help answer inquiries a biomedical expert would typically receive, such as naming the mechanisms causing a particular disease.

For example, if you asked a simple LLM alone to name the ingredients of a specific prescription drug, it may reply incorrectly. With the added expertise of a model that specializes in biomedical data, you’d get a more accurate answer. Co-LLM also alerts users where to double-check answers.

Another example of Co-LLM’s performance boost: When tasked with solving a math problem like “a3 · a2 if a=5,” the general-purpose model incorrectly calculated the answer to be 125. As Co-LLM trained the model to collaborate more with a large math LLM called Llemma, together they determined that the correct solution was 3,125.

Co-LLM gave more accurate replies than fine-tuned simple LLMs and untuned specialized models working independently. Co-LLM can guide two models that were trained differently to work together, whereas other effective LLM collaboration approaches, such as “Proxy Tuning,” need all of their component models to be trained similarly. Additionally, this baseline requires each model to be used simultaneously to produce the answer, whereas MIT’s algorithm simply activates its expert model for particular tokens, leading to more efficient generation.

When to ask the expert

The MIT researchers’ algorithm highlights that imitating human teamwork more closely can increase accuracy in multi-LLM collaboration. To further elevate its factual precision, the team may draw from human self-correction: They’re considering a more robust deferral approach that can backtrack when the expert model doesn’t give a correct response. This upgrade would allow Co-LLM to course-correct so the algorithm can still give a satisfactory reply.

The team would also like to update the expert model (via only training the base model) when new information is available, keeping answers as current as possible. This would allow Co-LLM to pair the most up-to-date information with strong reasoning power. Eventually, the model could assist with enterprise documents, using the latest information it has to update them accordingly. Co-LLM could also train small, private models to work with a more powerful LLM to improve documents that must remain within the server.

“Co-LLM presents an interesting approach for learning to choose between two models to improve efficiency and performance,” says Colin Raffel, associate professor at the University of Toronto and an associate research director at the Vector Institute, who wasn’t involved in the research. “Since routing decisions are made at the token-level, Co-LLM provides a granular way of deferring difficult generation steps to a more powerful model. The unique combination of model-token-level routing also provides a great deal of flexibility that similar methods lack. Co-LLM contributes to an important line of work that aims to develop ecosystems of specialized models to outperform expensive monolithic AI systems.”

Shen wrote the paper with four other CSAIL affiliates: PhD student Hunter Lang ’17, MEng ’18; former postdoc and Apple AI/ML researcher Bailin Wang; MIT assistant professor of electrical engineering and computer science Yoon Kim, and professor and Jameel Clinic member David Sontag PhD ’10, who are both part of MIT-IBM Watson AI Lab. Their research was supported, in part, by the National Science Foundation, The National Defense Science and Engineering Graduate (NDSEG) Fellowship, MIT-IBM Watson AI Lab, and Amazon. Their work was presented at the Annual Meeting of the Association for Computational Linguistics.

Method prevents an AI model from being overconfident about wrong answers

People use large language models for a huge array of tasks, from translating an article to identifying financial fraud. However, despite the incredible capabilities and versatility of these models, they sometimes generate inaccurate responses.

On top of that problem, the models can be overconfident about wrong answers or underconfident about correct ones, making it tough for a user to know when a model can be trusted.

Researchers typically calibrate a machine-learning model to ensure its level of confidence lines up with its accuracy. A well-calibrated model should have less confidence about an incorrect prediction, and vice-versa. But because large language models (LLMs) can be applied to a seemingly endless collection of diverse tasks, traditional calibration methods are ineffective.

Now, researchers from MIT and the MIT-IBM Watson AI Lab have introduced a calibration method tailored to large language models. Their method, called Thermometer, involves building a smaller, auxiliary model that runs on top of a large language model to calibrate it.

Thermometer is more efficient than other approaches — requiring less power-hungry computation — while preserving the accuracy of the model and enabling it to produce better-calibrated responses on tasks it has not seen before.

By enabling efficient calibration of an LLM for a variety of tasks, Thermometer could help users pinpoint situations where a model is overconfident about false predictions, ultimately preventing them from deploying that model in a situation where it may fail.

“With Thermometer, we want to provide the user with a clear signal to tell them whether a model’s response is accurate or inaccurate, in a way that reflects the model’s uncertainty, so they know if that model is reliable,” says Maohao Shen, an electrical engineering and computer science (EECS) graduate student and lead author of a paper on Thermometer.

Shen is joined on the paper by Gregory Wornell, the Sumitomo Professor of Engineering who leads the Signals, Information, and Algorithms Laboratory in the Research Laboratory for Electronics, and is a member of the MIT-IBM Watson AI Lab; senior author Soumya Ghosh, a research staff member in the MIT-IBM Watson AI Lab; as well as others at MIT and the MIT-IBM Watson AI Lab. The research was recently presented at the International Conference on Machine Learning.

Universal calibration

Since traditional machine-learning models are typically designed to perform a single task, calibrating them usually involves one task-specific method. On the other hand, since LLMs have the flexibility to perform many tasks, using a traditional method to calibrate that model for one task might hurt its performance on another task.

Calibrating an LLM often involves sampling from the model multiple times to obtain different predictions and then aggregating these predictions to obtain better-calibrated confidence. However, because these models have billions of parameters, the computational costs of such approaches rapidly add up.

“In a sense, large language models are universal because they can handle various tasks. So, we need a universal calibration method that can also handle many different tasks,” says Shen.

With Thermometer, the researchers developed a versatile technique that leverages a classical calibration method called temperature scaling to efficiently calibrate an LLM for a new task.

In this context, a “temperature” is a scaling parameter used to adjust a model’s confidence to be aligned with its prediction accuracy. Traditionally, one determines the right temperature using a labeled validation dataset of task-specific examples.

Since LLMs are often applied to new tasks, labeled datasets can be nearly impossible to acquire. For instance, a user who wants to deploy an LLM to answer customer questions about a new product likely does not have a dataset containing such questions and answers.

Instead of using a labeled dataset, the researchers train an auxiliary model that runs on top of an LLM to automatically predict the temperature needed to calibrate it for this new task.

They use labeled datasets of a few representative tasks to train the Thermometer model, but then once it has been trained, it can generalize to new tasks in a similar category without the need for additional labeled data.

A Thermometer model trained on a collection of multiple-choice question datasets, perhaps including one with algebra questions and one with medical questions, could be used to calibrate an LLM that will answer questions about geometry or biology, for instance.

“The aspirational goal is for it to work on any task, but we are not quite there yet,” Ghosh says.   

The Thermometer model only needs to access a small part of the LLM’s inner workings to predict the right temperature that will calibrate its prediction for data points of a specific task. 

An efficient approach

Importantly, the technique does not require multiple training runs and only slightly slows the LLM. Plus, since temperature scaling does not alter a model’s predictions, Thermometer preserves its accuracy.

When they compared Thermometer to several baselines on multiple tasks, it consistently produced better-calibrated uncertainty measures while requiring much less computation.

“As long as we train a Thermometer model on a sufficiently large number of tasks, it should be able to generalize well across any new task, just like a large language model, it is also a universal model,” Shen adds.

The researchers also found that if they train a Thermometer model for a smaller LLM, it can be directly applied to calibrate a larger LLM within the same family.

In the future, they want to adapt Thermometer for more complex text-generation tasks and apply the technique to even larger LLMs. The researchers also hope to quantify the diversity and number of labeled datasets one would need to train a Thermometer model so it can generalize to a new task.

This research was funded, in part, by the MIT-IBM Watson AI Lab.

A fast and flexible approach to help doctors annotate medical scans

To the untrained eye, a medical image like an MRI or X-ray appears to be a murky collection of black-and-white blobs. It can be a struggle to decipher where one structure (like a tumor) ends and another begins. 

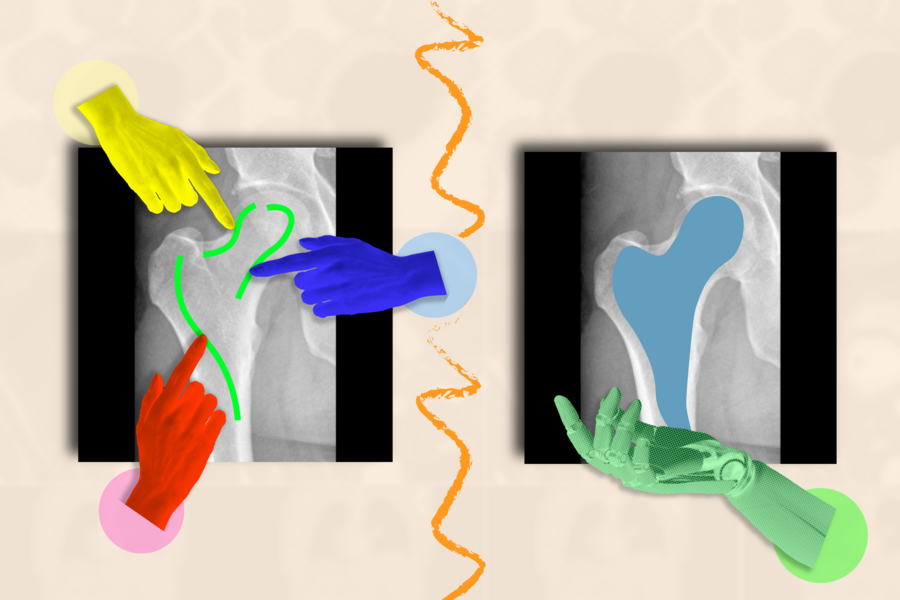
When trained to understand the boundaries of biological structures, AI systems can segment (or delineate) regions of interest that doctors and biomedical workers want to monitor for diseases and other abnormalities. Instead of losing precious time tracing anatomy by hand across many images, an artificial assistant could do that for them.

The catch? Researchers and clinicians must label countless images to train their AI system before it can accurately segment. For example, you’d need to annotate the cerebral cortex in numerous MRI scans to train a supervised model to understand how the cortex’s shape can vary in different brains.

Sidestepping such tedious data collection, researchers from MIT’s Computer Science and Artificial Intelligence Laboratory (CSAIL), Massachusetts General Hospital (MGH), and Harvard Medical School have developed the interactive “ScribblePrompt” framework: a flexible tool that can help rapidly segment any medical image, even types it hasn’t seen before. 

Instead of having humans mark up each picture manually, the team simulated how users would annotate over 50,000 scans, including MRIs, ultrasounds, and photographs, across structures in the eyes, cells, brains, bones, skin, and more. To label all those scans, the team used algorithms to simulate how humans would scribble and click on different regions in medical images. In addition to commonly labeled regions, the team also used superpixel algorithms, which find parts of the image with similar values, to identify potential new regions of interest to medical researchers and train ScribblePrompt to segment them. This synthetic data prepared ScribblePrompt to handle real-world segmentation requests from users.

“AI has significant potential in analyzing images and other high-dimensional data to help humans do things more productively,” says MIT PhD student Hallee Wong SM ’22, the lead author on a new paper about ScribblePrompt and a CSAIL affiliate. “We want to augment, not replace, the efforts of medical workers through an interactive system. ScribblePrompt is a simple model with the efficiency to help doctors focus on the more interesting parts of their analysis. It’s faster and more accurate than comparable interactive segmentation methods, reducing annotation time by 28 percent compared to Meta’s Segment Anything Model (SAM) framework, for example.”

ScribblePrompt’s interface is simple: Users can scribble across the rough area they’d like segmented, or click on it, and the tool will highlight the entire structure or background as requested. For example, you can click on individual veins within a retinal (eye) scan. ScribblePrompt can also mark up a structure given a bounding box.

Then, the tool can make corrections based on the user’s feedback. If you wanted to highlight a kidney in an ultrasound, you could use a bounding box, and then scribble in additional parts of the structure if ScribblePrompt missed any edges. If you wanted to edit your segment, you could use a “negative scribble” to exclude certain regions.

These self-correcting, interactive capabilities made ScribblePrompt the preferred tool among neuroimaging researchers at MGH in a user study. 93.8 percent of these users favored the MIT approach over the SAM baseline in improving its segments in response to scribble corrections. As for click-based edits, 87.5 percent of the medical researchers preferred ScribblePrompt.

ScribblePrompt was trained on simulated scribbles and clicks on 54,000 images across 65 datasets, featuring scans of the eyes, thorax, spine, cells, skin, abdominal muscles, neck, brain, bones, teeth, and lesions. The model familiarized itself with 16 types of medical images, including microscopies, CT scans, X-rays, MRIs, ultrasounds, and photographs.

“Many existing methods don’t respond well when users scribble across images because it’s hard to simulate such interactions in training. For ScribblePrompt, we were able to force our model to pay attention to different inputs using our synthetic segmentation tasks,” says Wong. “We wanted to train what’s essentially a foundation model on a lot of diverse data so it would generalize to new types of images and tasks.”

After taking in so much data, the team evaluated ScribblePrompt across 12 new datasets. Although it hadn’t seen these images before, it outperformed four existing methods by segmenting more efficiently and giving more accurate predictions about the exact regions users wanted highlighted.

“​​Segmentation is the most prevalent biomedical image analysis task, performed widely both in routine clinical practice and in research — which leads to it being both very diverse and a crucial, impactful step,” says senior author Adrian Dalca SM ’12, PhD ’16, CSAIL research scientist and assistant professor at MGH and Harvard Medical School. “ScribblePrompt was carefully designed to be practically useful to clinicians and researchers, and hence to substantially make this step much, much faster.”

“The majority of segmentation algorithms that have been developed in image analysis and machine learning are at least to some extent based on our ability to manually annotate images,” says Harvard Medical School professor in radiology and MGH neuroscientist Bruce Fischl, who was not involved in the paper. “The problem is dramatically worse in medical imaging in which our ‘images’ are typically 3D volumes, as human beings have no evolutionary or phenomenological reason to have any competency in annotating 3D images. ScribblePrompt enables manual annotation to be carried out much, much faster and more accurately, by training a network on precisely the types of interactions a human would typically have with an image while manually annotating. The result is an intuitive interface that allows annotators to naturally interact with imaging data with far greater productivity than was previously possible.”

Wong and Dalca wrote the paper with two other CSAIL affiliates: John Guttag, the Dugald C. Jackson Professor of EECS at MIT and CSAIL principal investigator; and MIT PhD student Marianne Rakic SM ’22. Their work was supported, in part, by Quanta Computer Inc., the Eric and Wendy Schmidt Center at the Broad Institute, the Wistron Corp., and the National Institute of Biomedical Imaging and Bioengineering of the National Institutes of Health, with hardware support from the Massachusetts Life Sciences Center.

Wong and her colleagues’ work will be presented at the 2024 European Conference on Computer Vision and was presented as an oral talk at the DCAMI workshop at the Computer Vision and Pattern Recognition Conference earlier this year. They were awarded the Bench-to-Bedside Paper Award at the workshop for ScribblePrompt’s potential clinical impact.

Student Spotlight: Krithik Ramesh

Today’s Student Spotlight focuses on Krithik Ramesh, a member of the class of 2025 majoring in 6-4, Artificial Intelligence and Decision-Making.

Tell us about your science hero or heroine.

My PI, Dr. Pardis Sabeti, has consistently been an inspiration of mine. Outside of her incredible accolades such as being TIME magazine’s “Person of the Year” for her efforts in fighting Ebola, she is genuinely the most empathetic, knowledgeable, and strong mentor anyone could ever ask for. While my interests lie in more computational pursuits, Pardis has helped me cultivate the skills to be a good researcher and an even better communicator, mentor, and person. Perfection is an impossible function, but I’d like to think that following in Pardis’s footsteps as a scientist and person is worth striving towards. It’s very rare that you get to work with your heroes, but I am incredibly fortunate that, because of MIT, I am able to work with the most influential person in my life. 

What’s your favorite building or room within MIT, and what’s special about it to you?

I’ve come to love stealing a recitation room in building 2 after a long day of classes. There’s something deeply comforting about sitting in a room and blasting music out loud, (and most probably dancing awkwardly), while working out pset problems on a black board. Particularly in the spring, it’s nice to look out of a recitation room and watch the sunset on Killian court. 

Tell us about your favorite game—it could be a computer game, a board game, a video game, a game you made up to make long car rides more interesting—anything!

Hands down my favorite game has to be Monopoly! When I was nine, my parents got me a collector’s edition Monopoly board for Christmas. When my grandfather would visit from India, we’d play for hours on end over the summer. Through tears I would ask him to make clearly unfavorable trades. As I grew older, I got really into the theory behind the game and watched videos on Markov Chain Monte Carlo (MCMC) simulations and learned optimal strategy (hint: the colors of the properties are kind of like a heatmap of the most landed on areas). To this day, I carry around the cowboy on a horse piece from that Monopoly set, as a reminder of the special times I had with my grandfather. 

Are you a re-reader or a re-watcher—and if so, what are your comfort books, shows, or movies?

I hope this resonates with many people, but I genuinely think I have memorized every episode of The Office. I have truthfully lost count, but I would estimate that I have watched the show around 7 times over. Both in high school and early parts of college, I used to throw on an episode (okay multiple episodes) as entertaining background noise while I worked. I am also the proud owner of a Dunder Mifflin shirt 😄. 

Tell me about one conversation that changed the trajectory of your life.

I spent a few months in New Zealand while attending the University of Auckland.  There, I had a transformative conversation with Zak Devey, one of the most cheerful people I’ve ever met. His positivity was infectious, and we talked about everything from great coffee spots to the meaning of research. He shared his belief that a life well-lived is where “passion meets purpose.”  Zak spoke about his family’s struggles with mental health and his dream of becoming a clinical psychologist, using his education to make a difference in his community.  His background and advice fundamentally changed the way I looked at research. It instilled in me a great sense of duty to conduct research that starts with understanding the problems that affect disenfranchised communities and developing salient solutions devised by the application of theory — Mens et Manus.

If you had to teach a really in-depth class about one niche topic, what would you pick?

I’d love to teach a special subject in Lego Star Wars History. Over the years, with “adult” money, I’ve started amassing Lego Star Wars sets for projects during an IAP or semester break. While not-so-patiently waiting for my sets to arrive, I have watched YouTube reviews and consumed the Lego Star Wars Visual Dictionary. Commemorating the 25th anniversary of Lego Star Wars, I am looking forward to teaching a deep dive course that combines Lego Star Wars sets with the rich lore of the Star Wars Universe. 

Do you have a bucket list? If so, share one or two of the items on it!

Easy. 

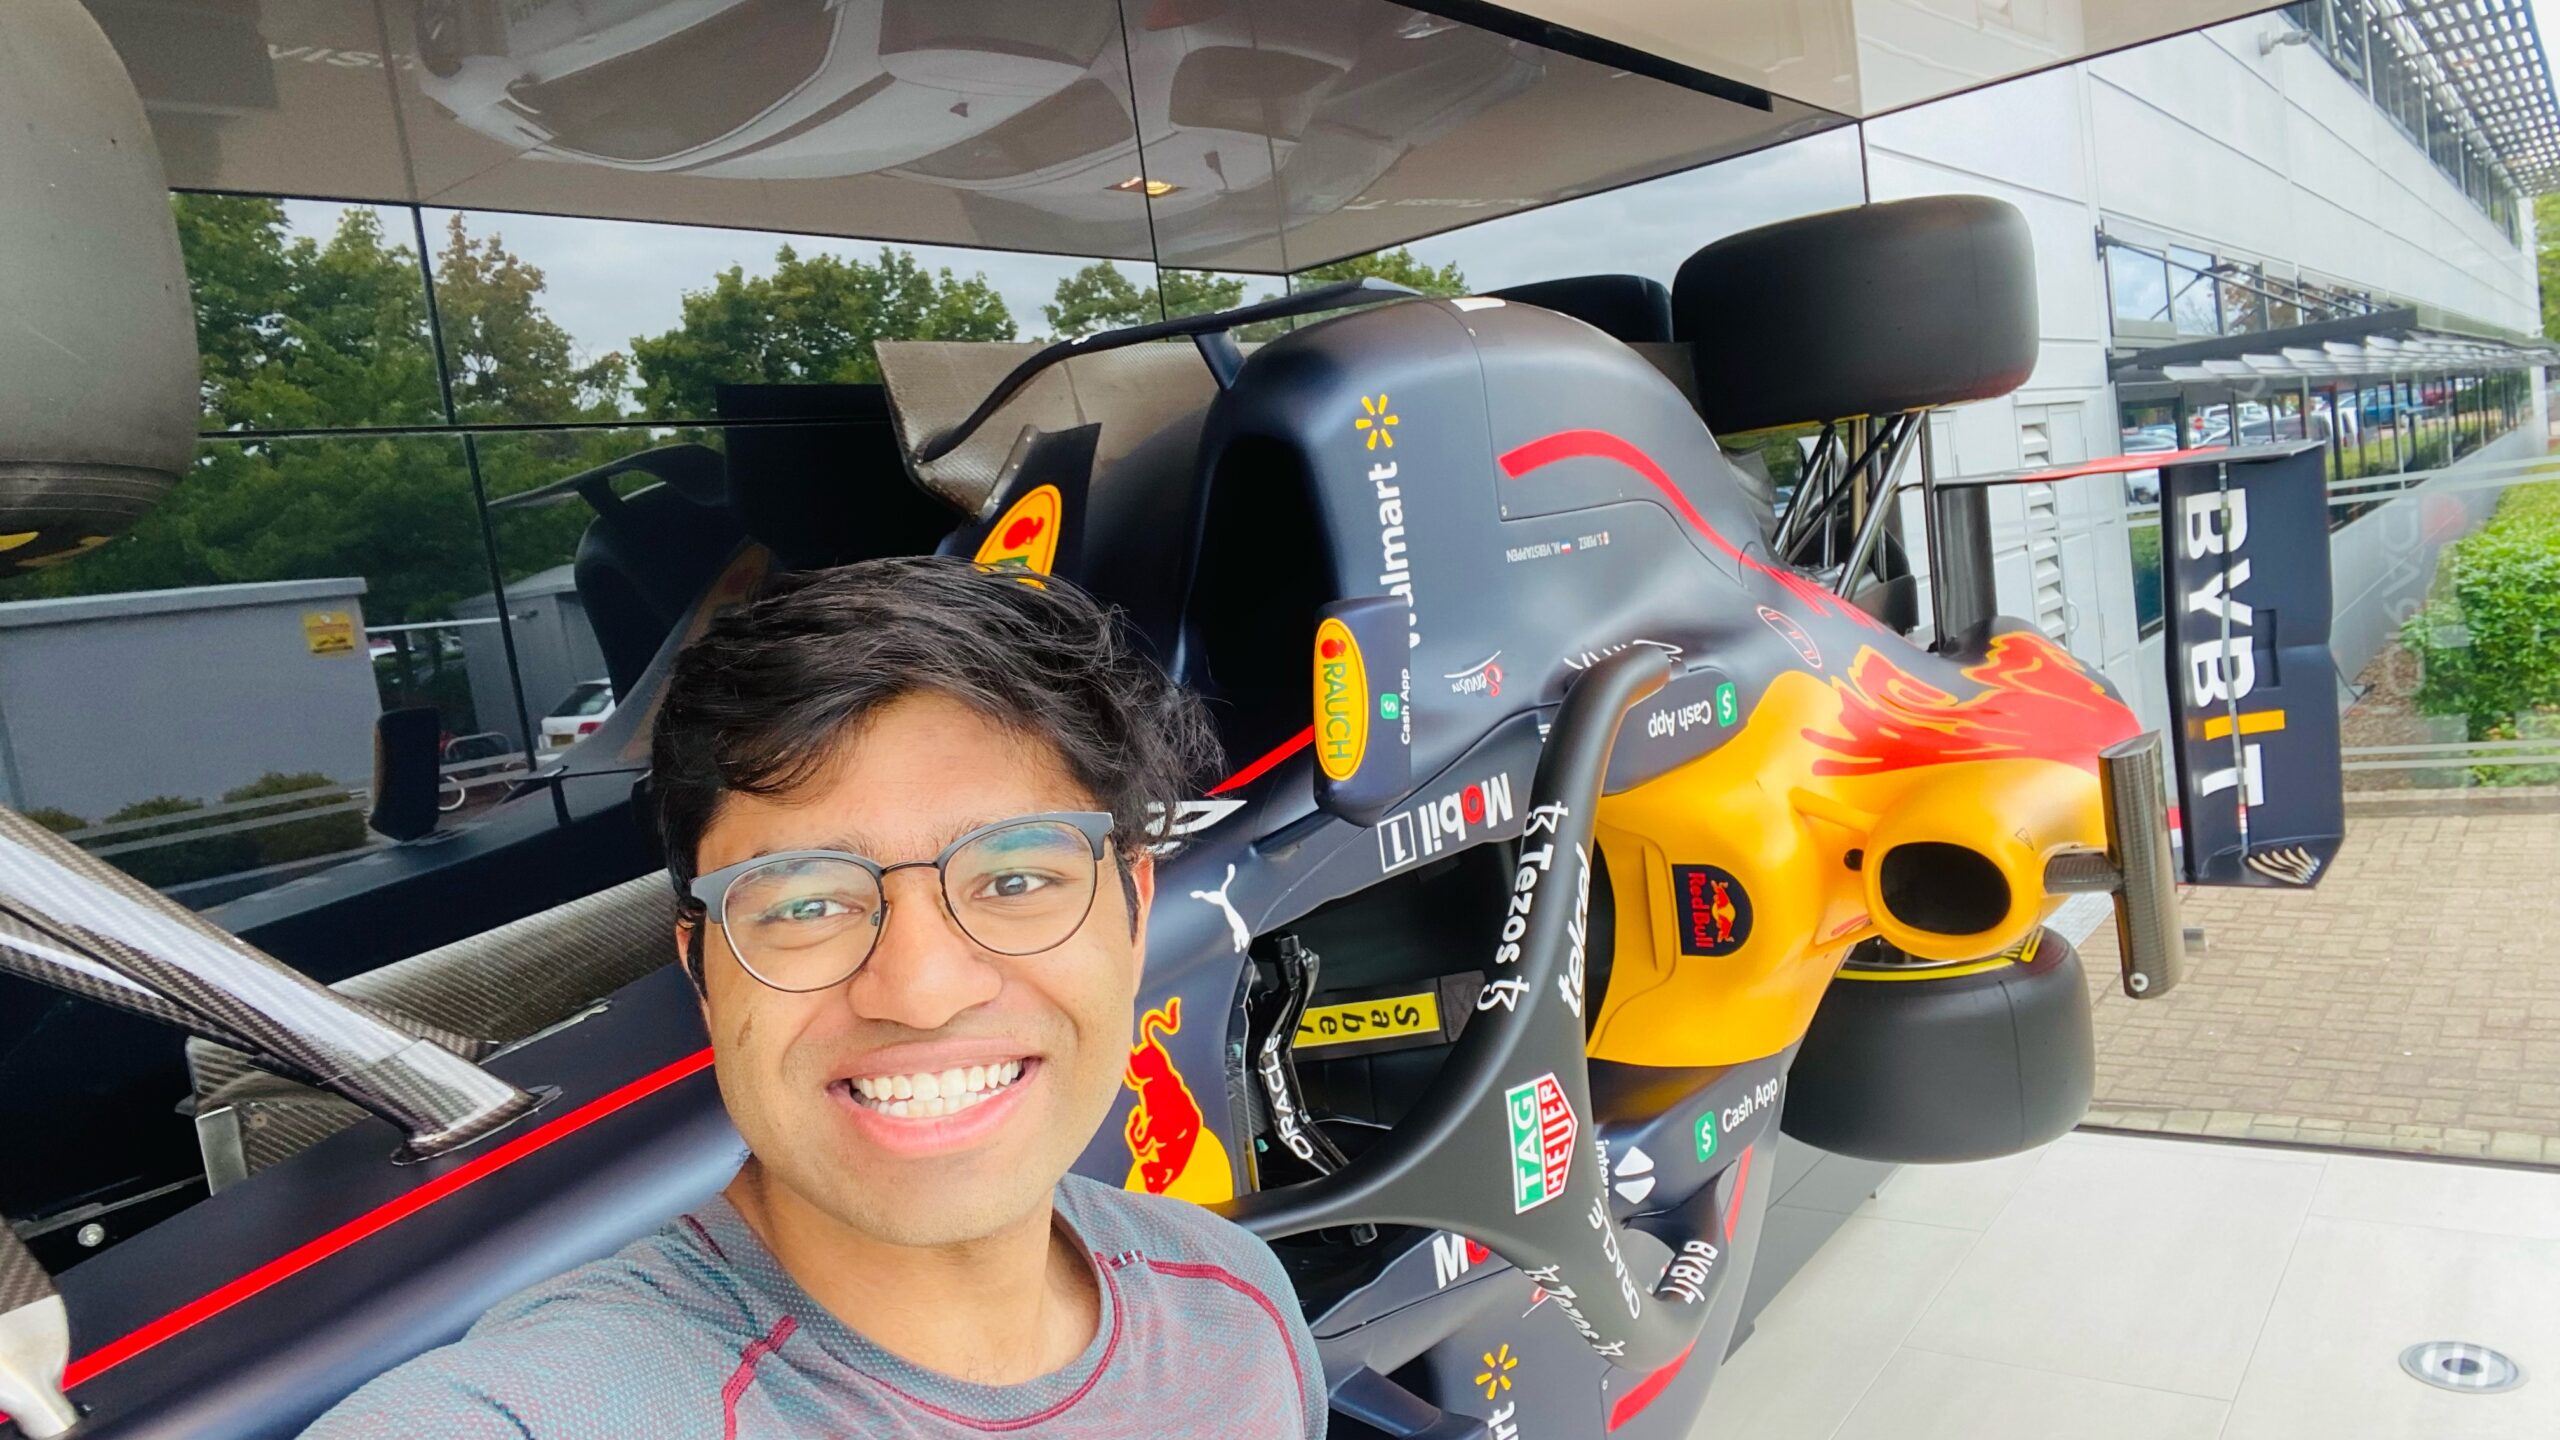
1. Take a selfie with a Quokka in Australia (recreate this photo specifically!)

2. See the Northern Lights in Iceland

3Qs: Dirk Englund on the quantum computing track within 6-5, “Electrical Engineering With Computing”.

Starting in Fall 2024, EECS is launching 6-5, “Electrical Engineering With Computing” as the sole new electrical engineering major. One of the signal changes of the new degree is the organization of upper-level classes into tracks, including an undergraduate engineering sequence in quantum engineering, where students learn the foundations of the quantum computing “stack” before creating their own quantum engineered systems in the lab.

Dirk Englund, Associate Professor in EECS, has been part of a team of instructors developing the quantum course sequence. “Back when I was an undergrad, I actually wanted to do cosmology. I wanted to understand how the universe works,” Englund says. “I went into the laboratory of one of my advisers, who had an atomic physics laboratory, and there on the optics table you could do experiments that looked at very fundamental questions like non-locality that I had thought were reserved for cosmology. That really pulled me in. So now I’m actually doing quantum information science in an electrical engineering and computer science department! We’re training the next generation of engineers because, after decades of work by different groups, we’re actually at the point where some of these technologies are getting deployed into the real world.” Those technologies range from quantum computers to quantum communications equipment to quantum sensors, all of which harness the surprising and bizarre principles of quantum mechanics, such as entanglement and non-locality of physics, to break new technological ground. 

Englund sat down with us to share more about the new quantum curriculum within electrical engineering. 

What’s important–and what excites you–about this quantum track?

Because basically every technology is ultimately limited by the rules of quantum mechanics, our students are going to have to become familiar with (and comfortable with working at) the limits of technology, which increasingly are hitting the limits of quantum mechanics.

We think it’s imperative that we have a rigorous course offering for our students, and that’s what we’re doing. In the fall semester, I joined my colleagues Karl Berggren and Kevin O’Brien to do the lecture portion of 6.2400, “Introduction to Quantum Systems Engineering”. Now, in spring, is the portion in which the students put what we learned into practice here in the laboratory. 

People come at this course from different angles; some people excel in the algorithms part, or physics, or in electrical engineering, and so when our projects form, you have a diversity of experiences and backgrounds to make a team that can do things that none of the individuals could pull off. That creates a lot of learning between the teams–and it’s exciting for us instructors as well.

How will 6-5 “Electrical Engineering With Computing” prepare students for careers in quantum engineering?

The interesting thing about quantum information science and technology is that you need to have an interdisciplinary view. It combines information theory and algorithms as well as electrical engineering and physics.  You can’t really understand how quantum computers work without understanding the algorithms, and you can’t understand the algorithms without understanding the physics, because the two of them are still so closely connected. 

To be effective, you have to know multiple disciplines.

How does this class fit into the broader EE quantum engineering track?

I’ve said before that the three pillars of quantum information science and technology are: new forms of computing; new forms of networking (or the Quantum Internet), and sensing. 

For each of these pillars, we have one or multiple labs that give students hands-on experience in these emerging fields. It’s quite unique; I am not aware of another offering of this kind anywhere within the US and probably even beyond. We’ve been able to bring together the resources thanks to strong support for the initiative from both the Department of EECS, but also from companies like Q Tools that have provided very significant financial and instrument support to make this class possible. 

Essentially, right now we’re developing the elementary building blocks of the next generation of technologies. What’s unique is that we’re getting our students to interact with the transistors and the elementary building blocks of, arguably, the revolutionary technologies of the 21st century.

3Qs: Jelena Notaros on the new Silicon Photonics class within 6-5, Electrical Engineering With Computing

Starting in Fall 2024, EECS is launching 6-5, “Electrical Engineering With Computing” as the sole new electrical engineering major. One of the signal changes of the new degree is the organization of upper-level classes into tracks, including an undergraduate engineering sequence in Electromagnetics and Photonics. Jelena Notaros, Assistant Professor in EECS, developed a new class included in that track, “Silicon Photonics”.

Let’s start with a really basic question. Why is the field of silicon photonics so exciting right now?

What gets me extremely excited about the field of silicon photonics is that we are developing photonic microsystems that have the potential to enable next-generation optical technologies that could facilitate revolutionary advances for numerous real-world applications, but we are still very grounded in electromagnetics, optics, and device physics – three core fundamental topics in electrical engineering. 

In the field of silicon photonics, we are leveraging the same processes that are normally used to fabricate standard computer chips. However, instead of fabricating electronic devices – transistors – on these chips and using them to manipulate electrical signals, we fabricate the chips to confine, guide, and manipulate light directly on the chip. Using this technology, we can integrate millions of micro-scale optical components into compact millimeter-scale chips – integrating optical systems that were once complex and bulky into very compact and flat form factors.

The initial driving applications for the field were in telecom and datacom. But, now, we’re starting to see new emerging applications of silicon photonics such as LiDAR sensors for autonomous systems, holographic augmented-reality and virtual-reality displays, interfacing to various types of qubits for quantum computing, and extremely sensitive chemical and biological sensors. There are so many exciting and high-impact applications that are beginning to be addressed with silicon photonics.

Tell me more about the new Silicon Photonics class that you developed. What were some of the challenges in developing a silicon-photonics lab class?

My students and I developed a new first-of-its-kind Silicon Photonics class for the MIT EECS department that introduces students to this exciting field. The course covers the foundational concepts behind silicon photonics grounded in electromagnetics, optics, and device physics; the design of silicon-photonics-based devices using both theoretical analysis and state-of-the-art simulation tools; the engineering of silicon-photonics-based circuits and systems for a variety of emerging application areas; the development of silicon-photonics-based fabrication platforms; and even experimental characterization through hands-on lab exercises with state-of-the-art equipment.

Normally, a silicon-photonics class offered elsewhere would just cover the theory and design aspects. But, for our class, we strived to go beyond just lecture-based learning by developing a class with hands-on labs, where the students can put their theoretical knowledge to practice by testing real cutting-edge silicon-photonics chips with industry-standard instrumentation.

Developing this class, and especially the hands-on lab aspect, took an enormous amount of effort. Not only did we develop all the class materials from scratch, including the syllabus, lectures, homework, simulation exercises, and lab exercises, but we also built a brand-new research-grade silicon-photonics teaching laboratory just for the class with three electronic-photonic probe stations and designed an accompanying custom silicon-photonics education chipset. This process required a lot of interaction with companies, including securing significant donations and discounts from many of them. We are thankful especially to Keysight, FormFactor, New Imaging Technologies, Ansys Lumerical, and Thorlabs for their support.

And, most importantly, I am personally incredibly grateful to all of my students who put in huge amount of time and effort to help develop this class, including Milica Notaros, Alex Sludds, Saumil Bandyopadhyay, Daniel DeSantis, Andres Garcia Coleto, Ashton Hattori, Sabrina Corsetti, and Tal Sneh.

How are students responding to this new class? 

It’s been just so incredibly rewarding for us to see so many students excited about the class. I think students are excited to have the opportunity to take a class where they can learn about a cutting-edge field, test real state-of-the-art chip hardware using industry-standard equipment, apply the core foundational concepts that they learned in their prior classes, and build up relevant expertise that they can use in their future industry or research careers.

We’re seeing students joining the class, not only from the electrical-engineering side, but also from computer science, physics, materials science, math, and aerospace engineering. We’ve even had quite a few students coming from other universities to MIT just to take the class. And what’s been really wonderful is seeing students at various stages in their careers, from freshmen undergraduate students through to senior graduate students and even postdoctoral scholars, taking the class. All standing at the same optical table. All learning about the incredible field of silicon photonics. And all getting excited about electrical-engineering hardware.

Toward a code-breaking quantum computer

The most recent email you sent was likely encrypted using a tried-and-true method that relies on the idea that even the fastest computer would be unable to efficiently break a gigantic number into factors.

Quantum computers, on the other hand, promise to rapidly crack complex cryptographic systems that a classical computer might never be able to unravel. This promise is based on a quantum factoring algorithm proposed in 1994 by Peter Shor, who is now a professor at MIT.

But while researchers have taken great strides in the last 30 years, scientists have yet to build a quantum computer powerful enough to run Shor’s algorithm.

As some researchers work to build larger quantum computers, others have been trying to improve Shor’s algorithm so it could run on a smaller quantum circuit. About a year ago, New York University computer scientist Oded Regev proposed a major theoretical improvement. His algorithm could run faster, but the circuit would require more memory.

Building off those results, MIT researchers have proposed a best-of-both-worlds approach that combines the speed of Regev’s algorithm with the memory-efficiency of Shor’s. This new algorithm is as fast as Regev’s, requires fewer quantum building blocks known as qubits, and has a higher tolerance to quantum noise, which could make it more feasible to implement in practice.

In the long run, this new algorithm could inform the development of novel encryption methods that can withstand the code-breaking power of quantum computers.

“If large-scale quantum computers ever get built, then factoring is toast and we have to find something else to use for cryptography. But how real is this threat? Can we make quantum factoring practical? Our work could potentially bring us one step closer to a practical implementation,” says Vinod Vaikuntanathan, the Ford Foundation Professor of Engineering, a member of the Computer Science and Artificial Intelligence Laboratory (CSAIL), and senior author of a paper describing the algorithm.

The paper’s lead author is Seyoon Ragavan, a graduate student in the MIT Department of Electrical Engineering and Computer Science. The research will be presented at the 2024 International Cryptology Conference.

Cracking cryptography

To securely transmit messages over the internet, service providers like email clients and messaging apps typically rely on RSA, an encryption scheme invented by MIT researchers Ron Rivest, Adi Shamir, and Leonard Adleman in the 1970s (hence the name “RSA”). The system is based on the idea that factoring a 2,048-bit integer (a number with 617 digits) is too hard for a computer to do in a reasonable amount of time.

That idea was flipped on its head in 1994 when Shor, then working at Bell Labs, introduced an algorithm which proved that a quantum computer could factor quickly enough to break RSA cryptography.

“That was a turning point. But in 1994, nobody knew how to build a large enough quantum computer. And we’re still pretty far from there. Some people wonder if they will ever be built,” says Vaikuntanathan.

It is estimated that a quantum computer would need about 20 million qubits to run Shor’s algorithm. Right now, the largest quantum computers have around 1,100 qubits.

A quantum computer performs computations using quantum circuits, just like a classical computer uses classical circuits. Each quantum circuit is composed of a series of operations known as quantum gates. These quantum gates utilize qubits, which are the smallest building blocks of a quantum computer, to perform calculations.

But quantum gates introduce noise, so having fewer gates would improve a machine’s performance. Researchers have been striving to enhance Shor’s algorithm so it could be run on a smaller circuit with fewer quantum gates.

That is precisely what Regev did with the circuit he proposed a year ago.

“That was big news because it was the first real improvement to Shor’s circuit from 1994,” Vaikuntanathan says.

The quantum circuit Shor proposed has a size proportional to the square of the number being factored. That means if one were to factor a 2,048-bit integer, the circuit would need millions of gates.

Regev’s circuit requires significantly fewer quantum gates, but it needs many more qubits to provide enough memory. This presents a new problem.

“In a sense, some types of qubits are like apples or oranges. If you keep them around, they decay over time. You want to minimize the number of qubits you need to keep around,” explains Vaikuntanathan.

He heard Regev speak about his results at a workshop last August. At the end of his talk, Regev posed a question: Could someone improve his circuit so it needs fewer qubits? Vaikuntanathan and Ragavan took up that question.

Quantum ping-pong

To factor a very large number, a quantum circuit would need to run many times, performing operations that involve computing powers, like 2 to the power of 100.

But computing such large powers is costly and difficult to perform on a quantum computer, since quantum computers can only perform reversible operations. Squaring a number is not a reversible operation, so each time a number is squared, more quantum memory must be added to compute the next square.

The MIT researchers found a clever way to compute exponents using a series of Fibonacci numbers that requires simple multiplication, which is reversible, rather than squaring. Their method needs just two quantum memory units to compute any exponent.

“It is kind of like a ping-pong game, where we start with a number and then bounce back and forth, multiplying between two quantum memory registers,” Vaikuntanathan adds.

They also tackled the challenge of error correction. The circuits proposed by Shor and Regev require every quantum operation to be correct for their algorithm to work, Vaikuntanathan says. But error-free quantum gates would be infeasible on a real machine.

They overcame this problem using a technique to filter out corrupt results and only process the right ones.

The end-result is a circuit that is significantly more memory-efficient. Plus, their error correction technique would make the algorithm more practical to deploy.

“The authors resolve the two most important bottlenecks in the earlier quantum factoring algorithm. Although still not immediately practical, their work brings quantum factoring algorithms closer to reality,” adds Regev.

In the future, the researchers hope to make their algorithm even more efficient and, someday, use it to test factoring on a real quantum circuit.

“The elephant-in-the-room question after this work is: Does it actually bring us closer to breaking RSA cryptography? That is not clear just yet; these improvements currently only kick in when the integers are much larger than 2,048 bits. Can we push this algorithm and make it more feasible than Shor’s even for 2,048-bit integers?” says Ragavan.

This work is funded by an Akamai Presidential Fellowship, the U.S. Defense Advanced Research Projects Agency, the National Science Foundation, the MIT-IBM Watson AI Lab, a Thornton Family Faculty Research Innovation Fellowship, and a Simons Investigator Award.

A framework for solving parabolic partial differential equations

Computer graphics and geometry processing research provide the tools needed to simulate physical phenomena like fire and flames, aiding the creation of visual effects in video games and movies as well as the fabrication of complex geometric shapes using tools like 3D printing.

Under the hood, mathematical problems called partial differential equations (PDEs) model these natural processes. Among the many PDEs used in physics and computer graphics, a class called second-order parabolic PDEs explain how phenomena can become smooth over time. The most famous example in this class is the heat equation, which predicts how heat diffuses along a surface or in a volume over time.

Researchers in geometry processing have designed numerous algorithms to solve these problems on curved surfaces, but their methods often apply only to linear problems or to a single PDE. A more general approach by researchers from MIT’s Computer Science and Artificial Intelligence Laboratory (CSAIL) tackles a general class of these potentially nonlinear problems. 

In a paper recently published in the Transactions on Graphics journal and presented at the SIGGRAPH conference, they describe an algorithm that solves different nonlinear parabolic PDEs on triangle meshes by splitting them into three simpler equations that can be solved with techniques graphics researchers already have in their software toolkit. This framework can help better analyze shapes and model complex dynamical processes.

“We provide a recipe: If you want to numerically solve a second-order parabolic PDE, you can follow a set of three steps,” says lead author Leticia Mattos Da Silva SM ’23, an MIT PhD student in electrical engineering and computer science (EECS) and CSAIL affiliate. “For each of the steps in this approach, you’re solving a simpler problem using simpler tools from geometry processing, but at the end, you get a solution to the more challenging second-order parabolic PDE.”

To accomplish this, Da Silva and her coauthors used Strang splitting, a technique that allows geometry processing researchers to break the PDE down into problems they know how to solve efficiently.

First, their algorithm advances a solution forward in time by solving the heat equation (also called the “diffusion equation”), which models how heat from a source spreads over a shape. Picture using a blow torch to warm up a metal plate — this equation describes how heat from that spot would diffuse over it. 
This step can be completed easily with linear algebra.

Now, imagine that the parabolic PDE has additional nonlinear behaviors that are not described by the spread of heat. This is where the second step of the algorithm comes in: it accounts for the nonlinear piece by solving a Hamilton-Jacobi (HJ) equation, a first-order nonlinear PDE. 

While generic HJ equations can be hard to solve, Mattos Da Silva and coauthors prove that their splitting method applied to many important PDEs yields an HJ equation that can be solved via convex optimization algorithms. Convex optimization is a standard tool for which researchers in geometry processing already have efficient and reliable software. In the final step, the algorithm advances a solution forward in time using the heat equation again to advance the more complex second-order parabolic PDE forward in time.


Among other applications, the framework could help simulate fire and flames more efficiently. “There’s a huge pipeline that creates a video with flames being simulated, but at the heart of it is a PDE solver,” says Mattos Da Silva. For these pipelines, an essential step is solving the G-equation, a nonlinear parabolic PDE that models the front propagation of the flame and can be solved using the researchers’ framework.

The team’s algorithm can also solve the diffusion equation in the logarithmic domain, where it becomes nonlinear. Senior author Justin Solomon, associate professor of EECS and leader of the CSAIL Geometric Data Processing Group, previously developed a state-of-the-art technique for optimal transport that requires taking the logarithm of the result of heat diffusion. Mattos Da Silva’s framework provided more reliable computations by doing diffusion directly in the logarithmic domain. This enabled a more stable way to, for example, find a geometric notion of average among distributions on surface meshes like a model of a koala.

Even though their framework focuses on general, nonlinear problems, it can also be used to solve linear PDE. For instance, the method solves the Fokker-Planck equation, where heat diffuses in a linear way, but there are additional terms that drift in the same direction heat is spreading. In a straightforward application, the approach modeled how swirls would evolve over the surface of a triangulated sphere. The result resembles purple-and-brown latte art.

The researchers note that this project is a starting point for tackling the nonlinearity in other PDEs that appear in graphics and geometry processing head-on. For example, they focused on static surfaces but would like to apply their work to moving ones, too. Moreover, their framework solves problems involving a single parabolic PDE, but the team would also like to tackle problems involving coupled parabolic PDE. These types of problems arise in biology and chemistry, where the equation describing the evolution of each agent in a mixture, for example, is linked to the others’ equations.

Mattos Da Silva and Solomon wrote the paper with Oded Stein, assistant professor at the University of Southern California’s Viterbi School of Engineering. Their work was supported, in part, by an MIT Schwarzman College of Computing Fellowship funded by Google, a MathWorks Fellowship, the Swiss National Science Foundation, the U.S. Army Research Office, the U.S. Air Force Office of Scientific Research, the U.S. National Science Foundation, MIT-IBM Watson AI Lab, the Toyota-CSAIL Joint Research Center, Adobe Systems, and Google Research.